Every enterprise inherits a fleet, not a blank slate. Servers were launched months ago by different teams — no consistent tagging, unknown patch state, no baseline assigned. You can't patch what you can't identify.
Week 3 of my 52-week AWS lab solves both problems: a self-service platform where an ops engineer submits a ServiceNow ticket to either onboard an unmanaged EC2 instance into the managed fleet, or trigger a patch run across the entire environment. The ticket closes itself with a full compliance report. Zero SSH. Zero manual steps.
📋 In This Post
Lab Overview
Cloud Services and Concepts
| Service | Purpose here | What it is |
|---|---|---|
| AWS Systems Manager | Does the patching, and reports who is compliant | A set of tools for managing instances through an agent already on them: running commands, applying patches and reporting what state each one is in. |
| Patch Manager and patch baselines | Decides what "patched" means, per group | A baseline is the rule for which patches are approved; a patch group is the tag that says which baseline an instance follows. |
| Maintenance window | Decides when patching may happen | A recurring schedule Systems Manager runs tasks inside, so patching lands in a window someone has agreed to rather than whenever a ticket arrives. |
| AWS Step Functions | Routes the three request types and keeps the audit trail | Runs a workflow as an explicit state machine, so each step, its retry behaviour and its failure path are declared rather than buried in code. |
| AWS Lambda | Receives the webhook, onboards, reports back | Runs a piece of code on demand with no server to manage. You are billed per request and per millisecond it runs. |
| Amazon API Gateway | The signed endpoint ServiceNow calls | A managed front door that accepts HTTP requests and forwards them to a backend. |
| VPC interface endpoints | Lets private instances reach Systems Manager with no NAT gateway | Private doors from your network to an AWS service. Traffic reaches the service without crossing the internet, and no per-GB NAT charge applies. |
One idea runs through the build: in Systems Manager a tag is not
documentation, it is configuration. PatchGroup is
what binds an instance to a baseline, so an untagged instance is not
mis-patched — it is unmanaged, and reports nothing at all.
Architecture and Workflow
Prerequisites
| Requirement | Why | How to check |
|---|---|---|
| The SSM agent running, with an instance profile that allows it | Systems Manager reaches an instance through its agent and the agent's role. Without the role the instance is simply invisible, with no error anywhere | It appears in Fleet Manager as Online |
| A network path to the Systems Manager endpoints | The agent has to reach the service. This build uses VPC interface endpoints rather than a NAT gateway, which removes the per-GB charge entirely | The instance registers without a public route |
A PatchGroup tag on anything you expect to be patched | The tag is what associates an instance with a baseline. An untagged instance reports no compliance state rather than a bad one | Patch Manager lists the instance against a baseline |
| A shared secret for the webhook | The endpoint accepts only signed requests | Held as a sensitive variable, never in the repo |
Implementation
The Onboard Story — Making an Invisible Instance Visible
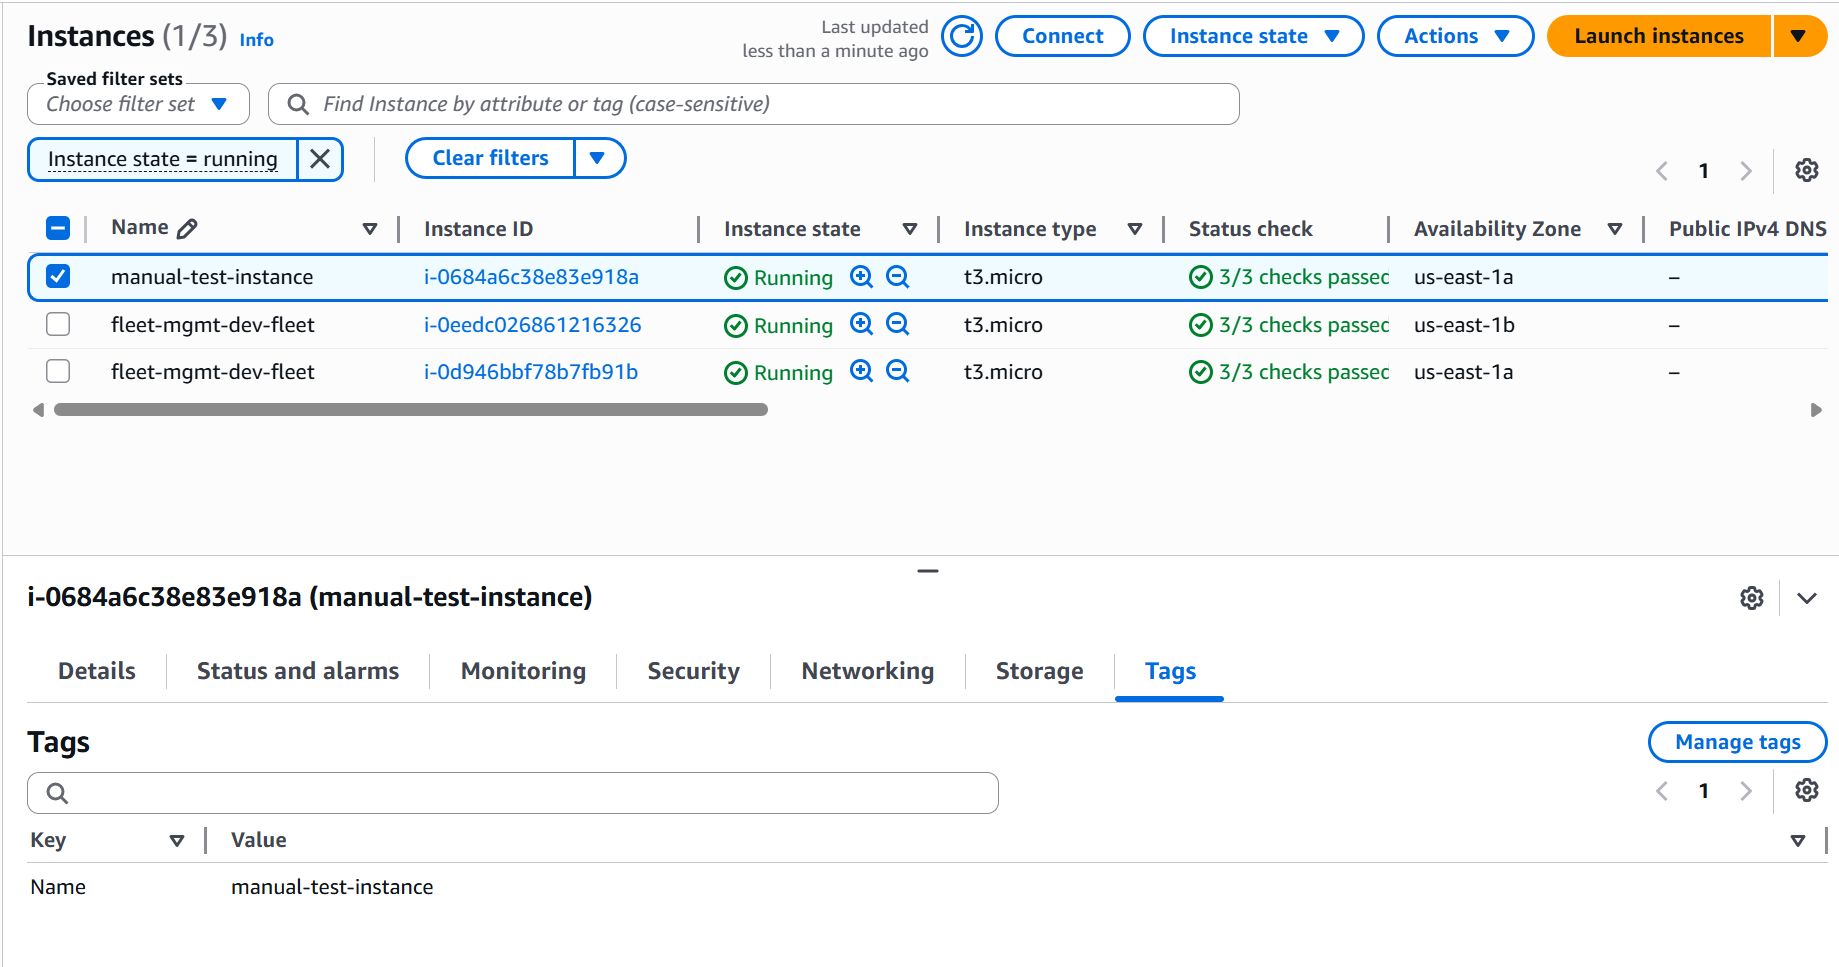
This is the most important feature of Week 3. I created an EC2 instance manually — the way most instances in a real enterprise already exist. No PatchGroup tag, no ManagedBy tag. Completely invisible to Patch Manager from a management perspective.
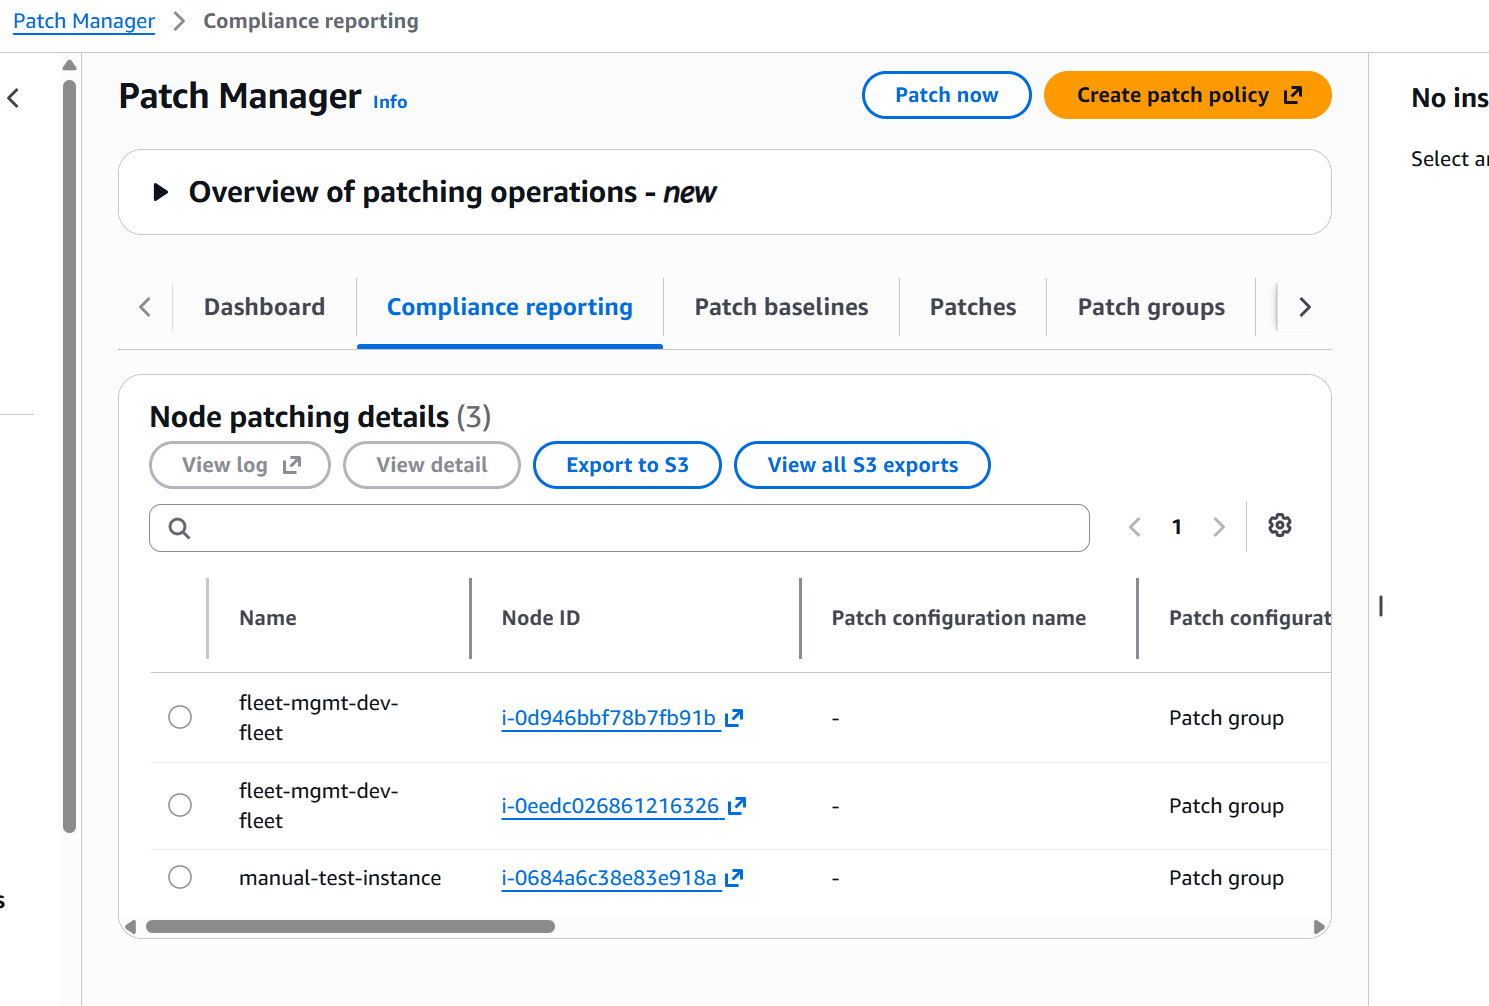
In Patch Manager, the instance appears but has no patch baseline assigned — Patch configuration name shows "-". It's visible but unmanaged.
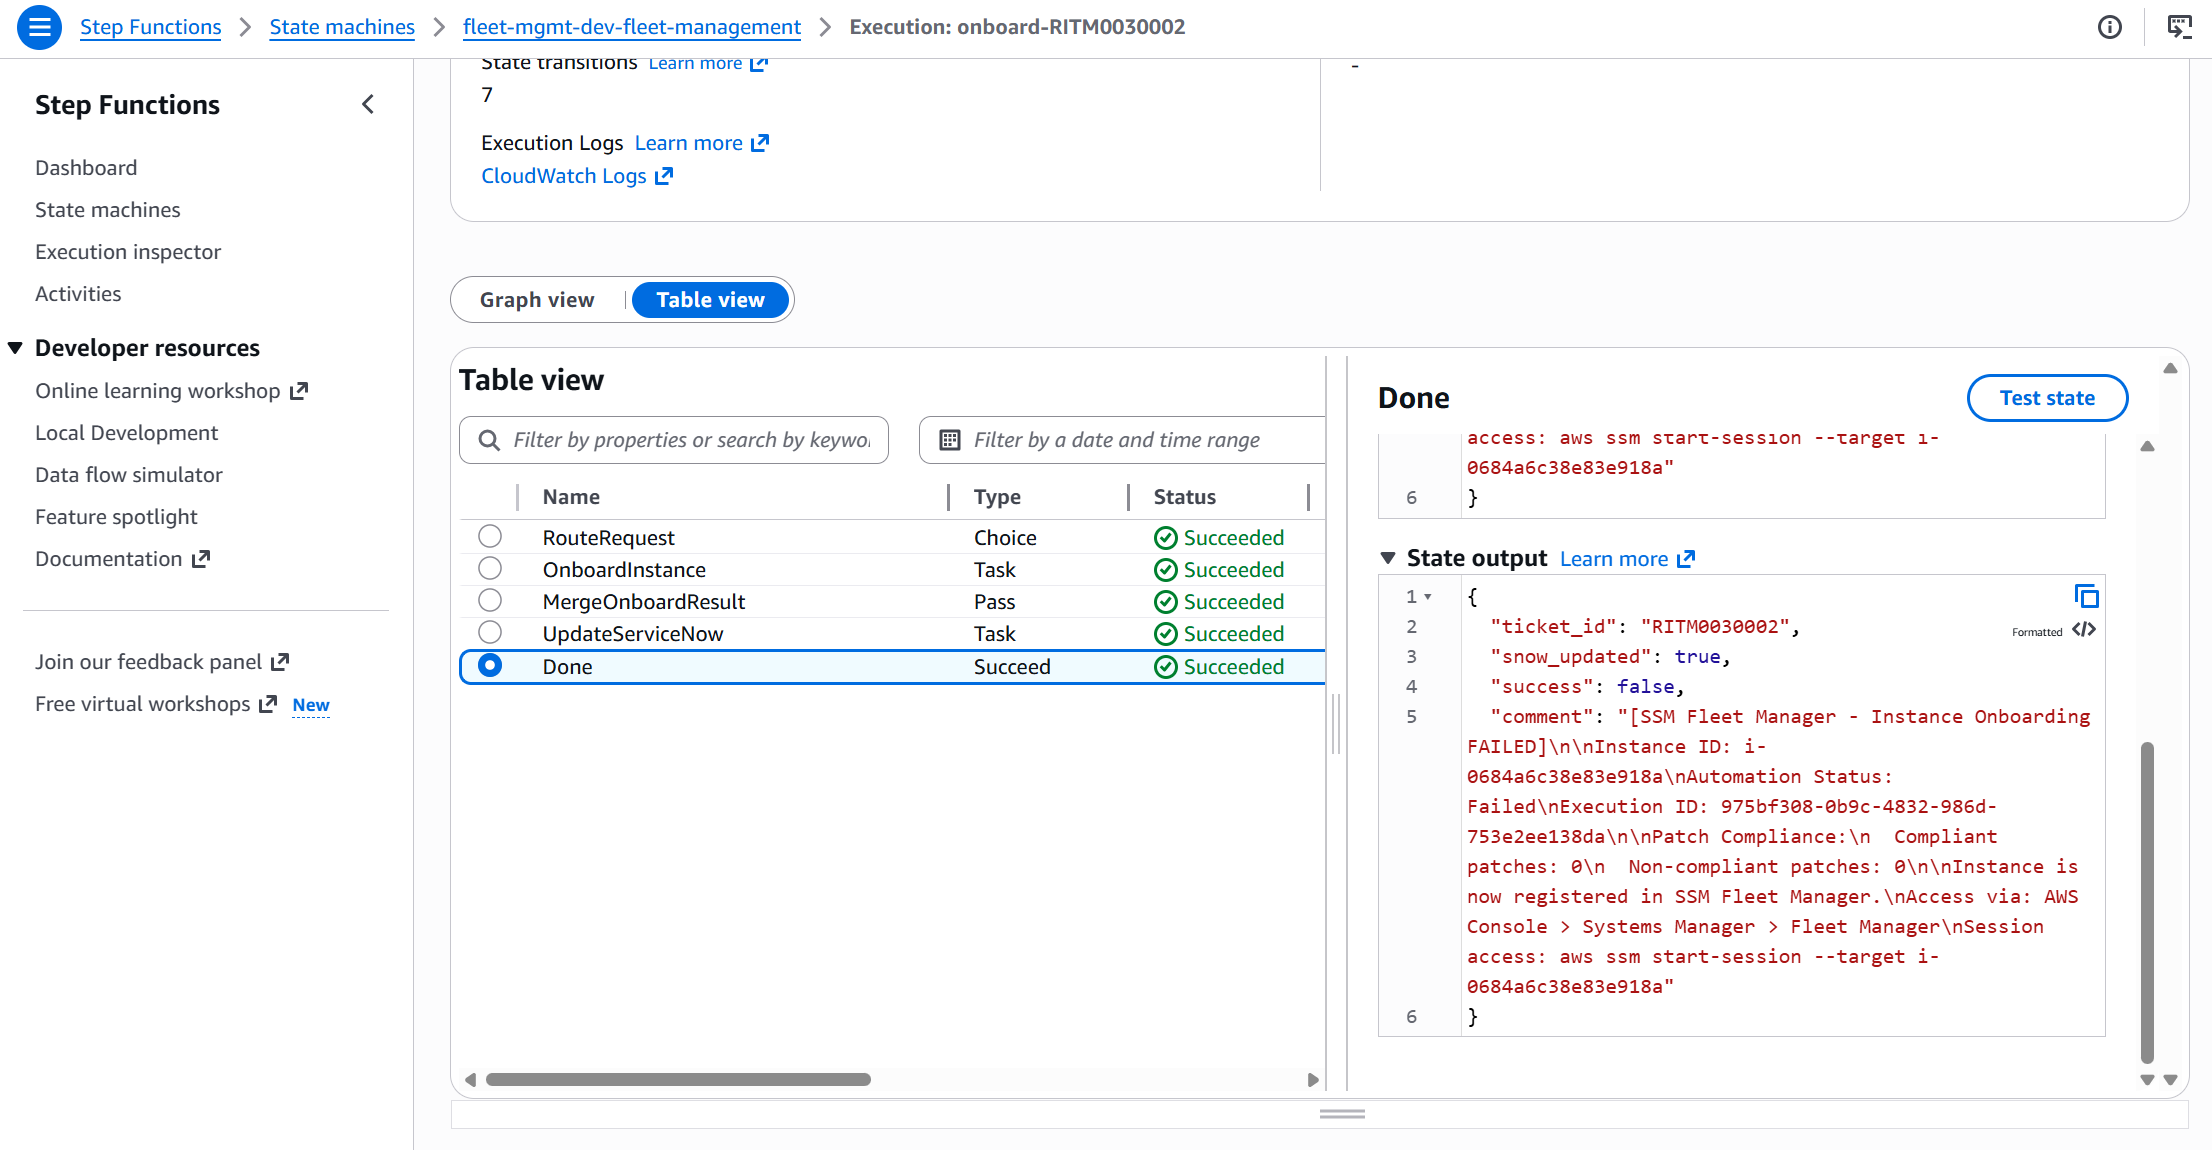
One onboard ticket changes everything. The SSM Automation runbook runs 5 steps:
- Wait for SSM agent to come online
- Apply tags —
PatchGroup=fleet-mgmt-dev-linux,ManagedBy=fleet-mgmt-dev,OnboardedAt=timestamp - Run baseline config via Run Command (yum update, confirm SSM agent running)
- Run initial patch scan to establish compliance baseline
- Collect compliance summary and return results
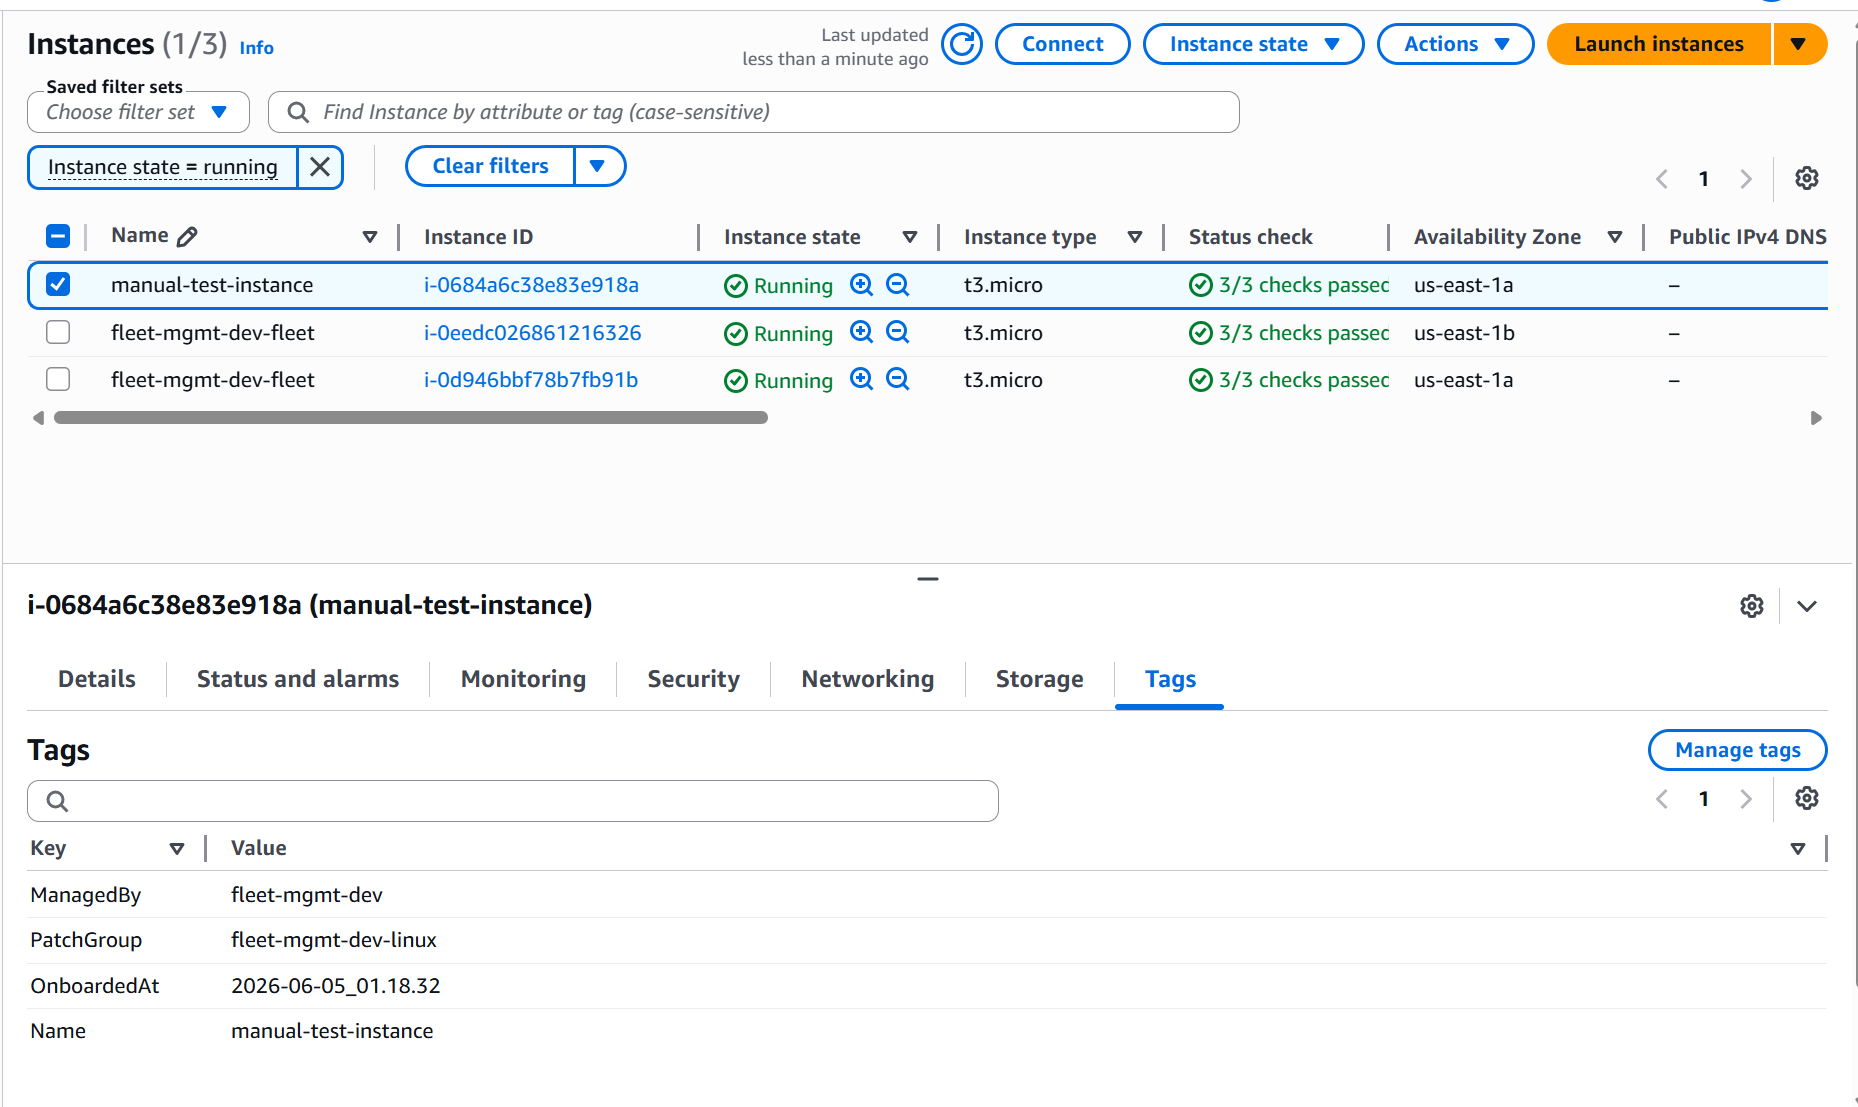
After onboard — all three tags applied automatically. The instance is now a first-class member of the managed fleet.
Patching All Three Instances in One Operation
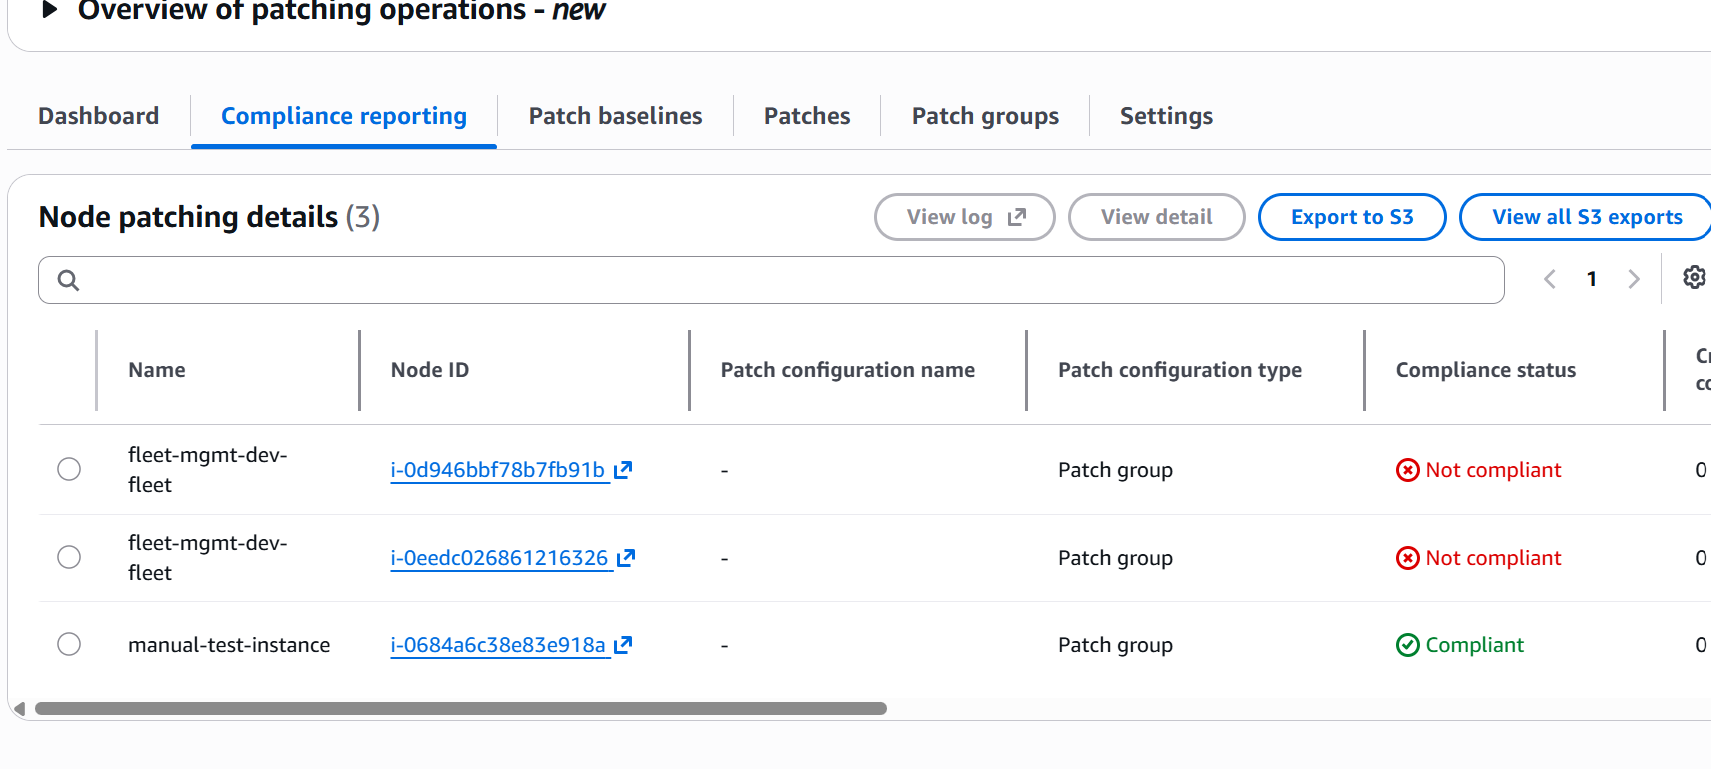
With the manual instance onboarded, all three share PatchGroup=fleet-mgmt-dev-linux. A single Install request patches all of them simultaneously — the platform can't tell which instances were ASG-launched and which was manually created.
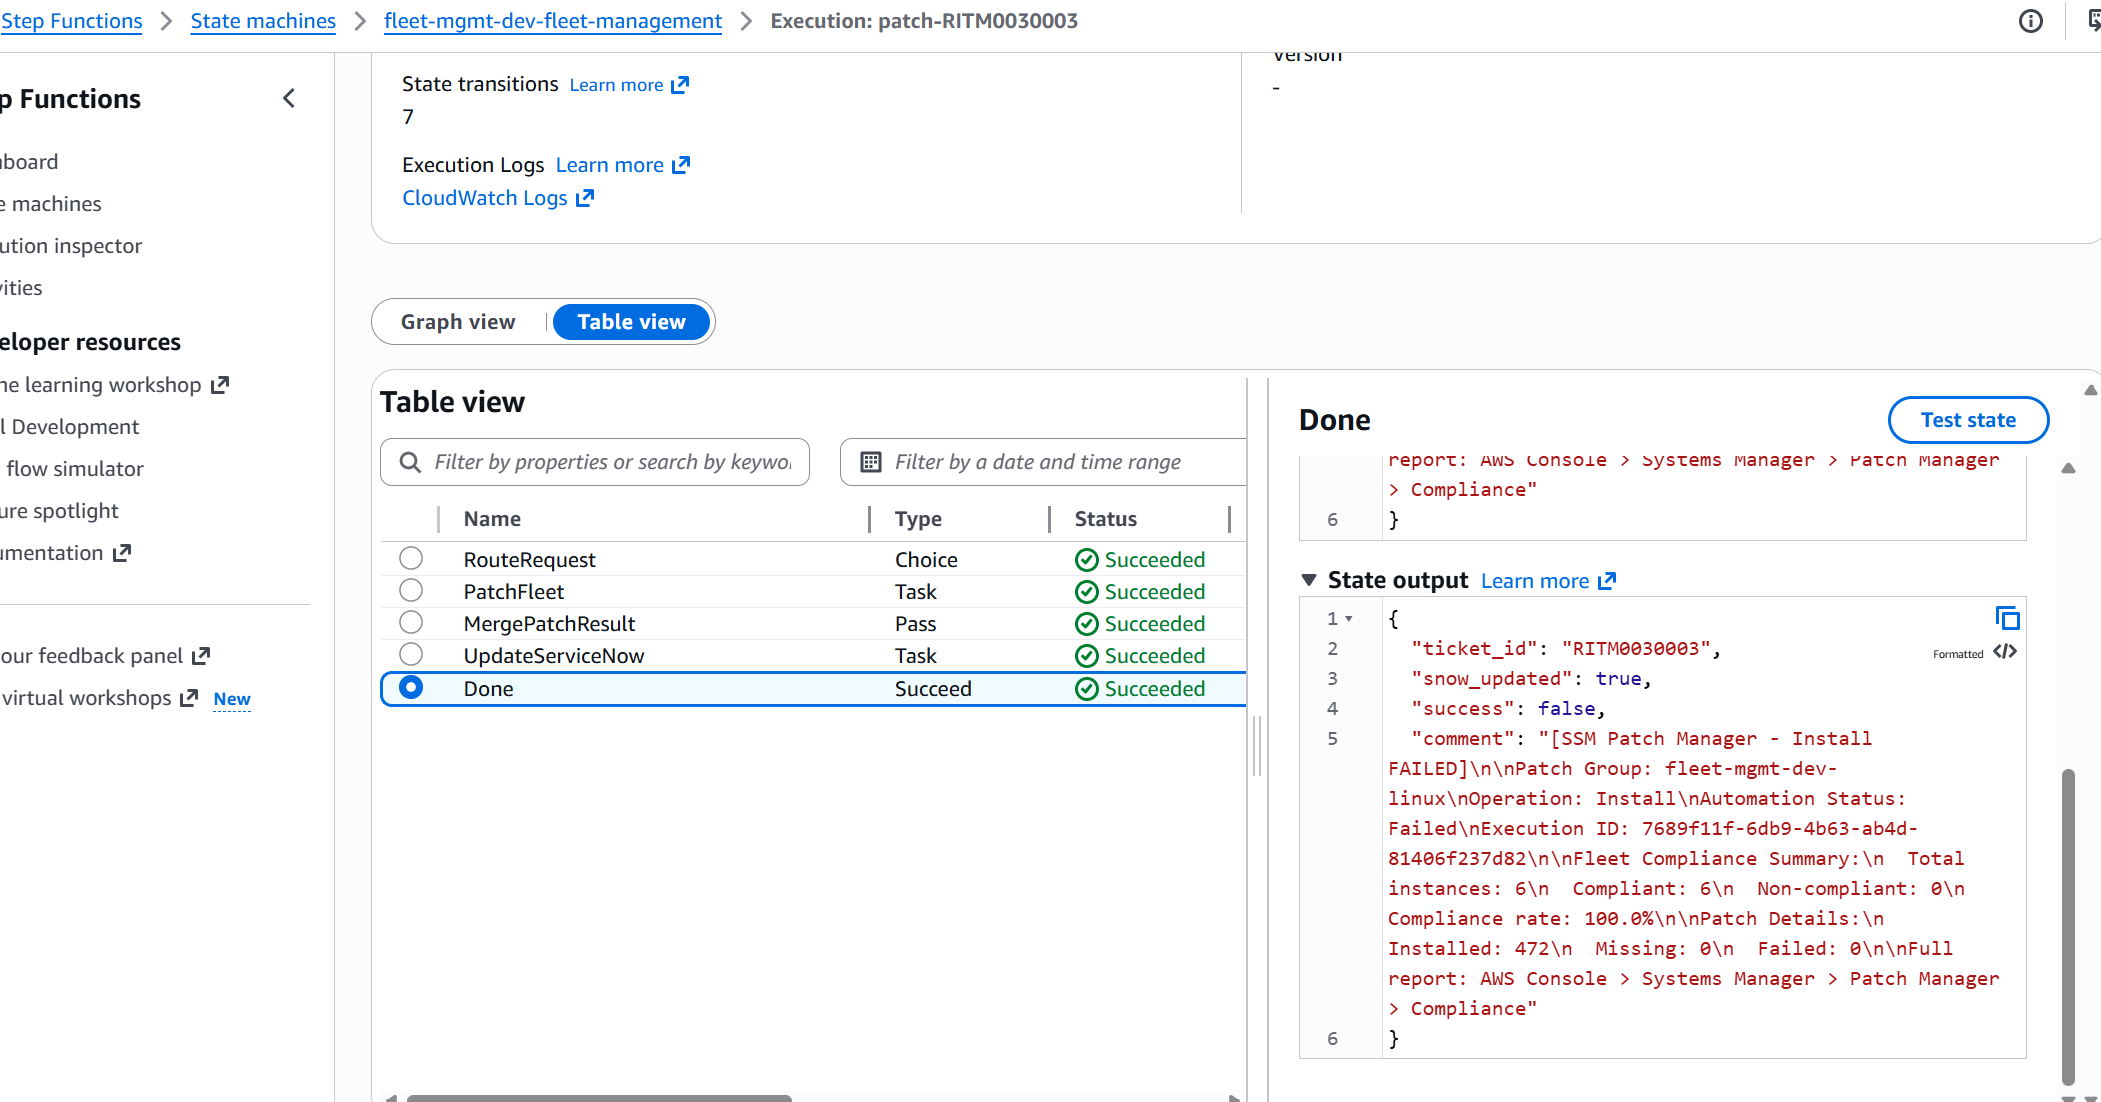
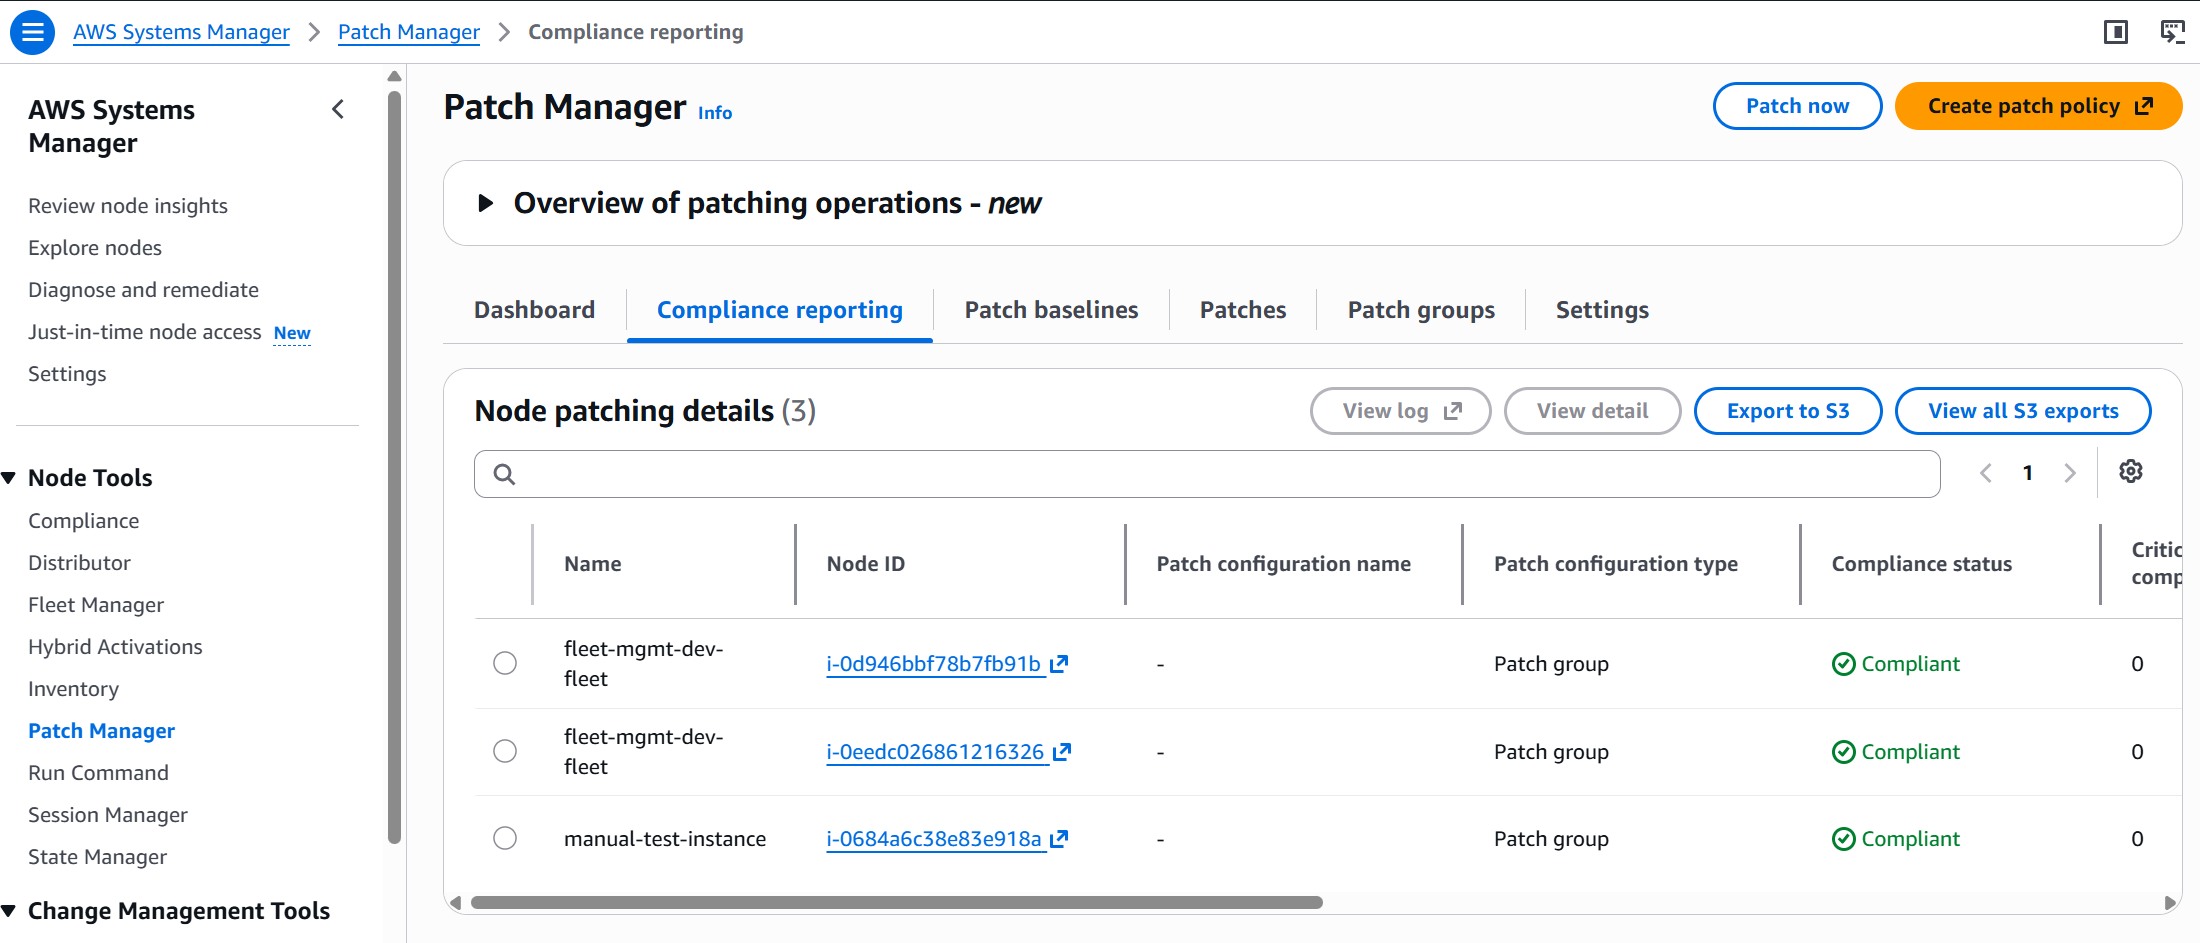
Result: all 3 instances fully patched. 472 patches installed across the fleet. 0 missing. 0 failed.
ServiceNow Integration — End to End
When fully wired, a user never touches AWS. They open the Service Catalog, fill in a form, and submit. The entire flow is invisible to them.
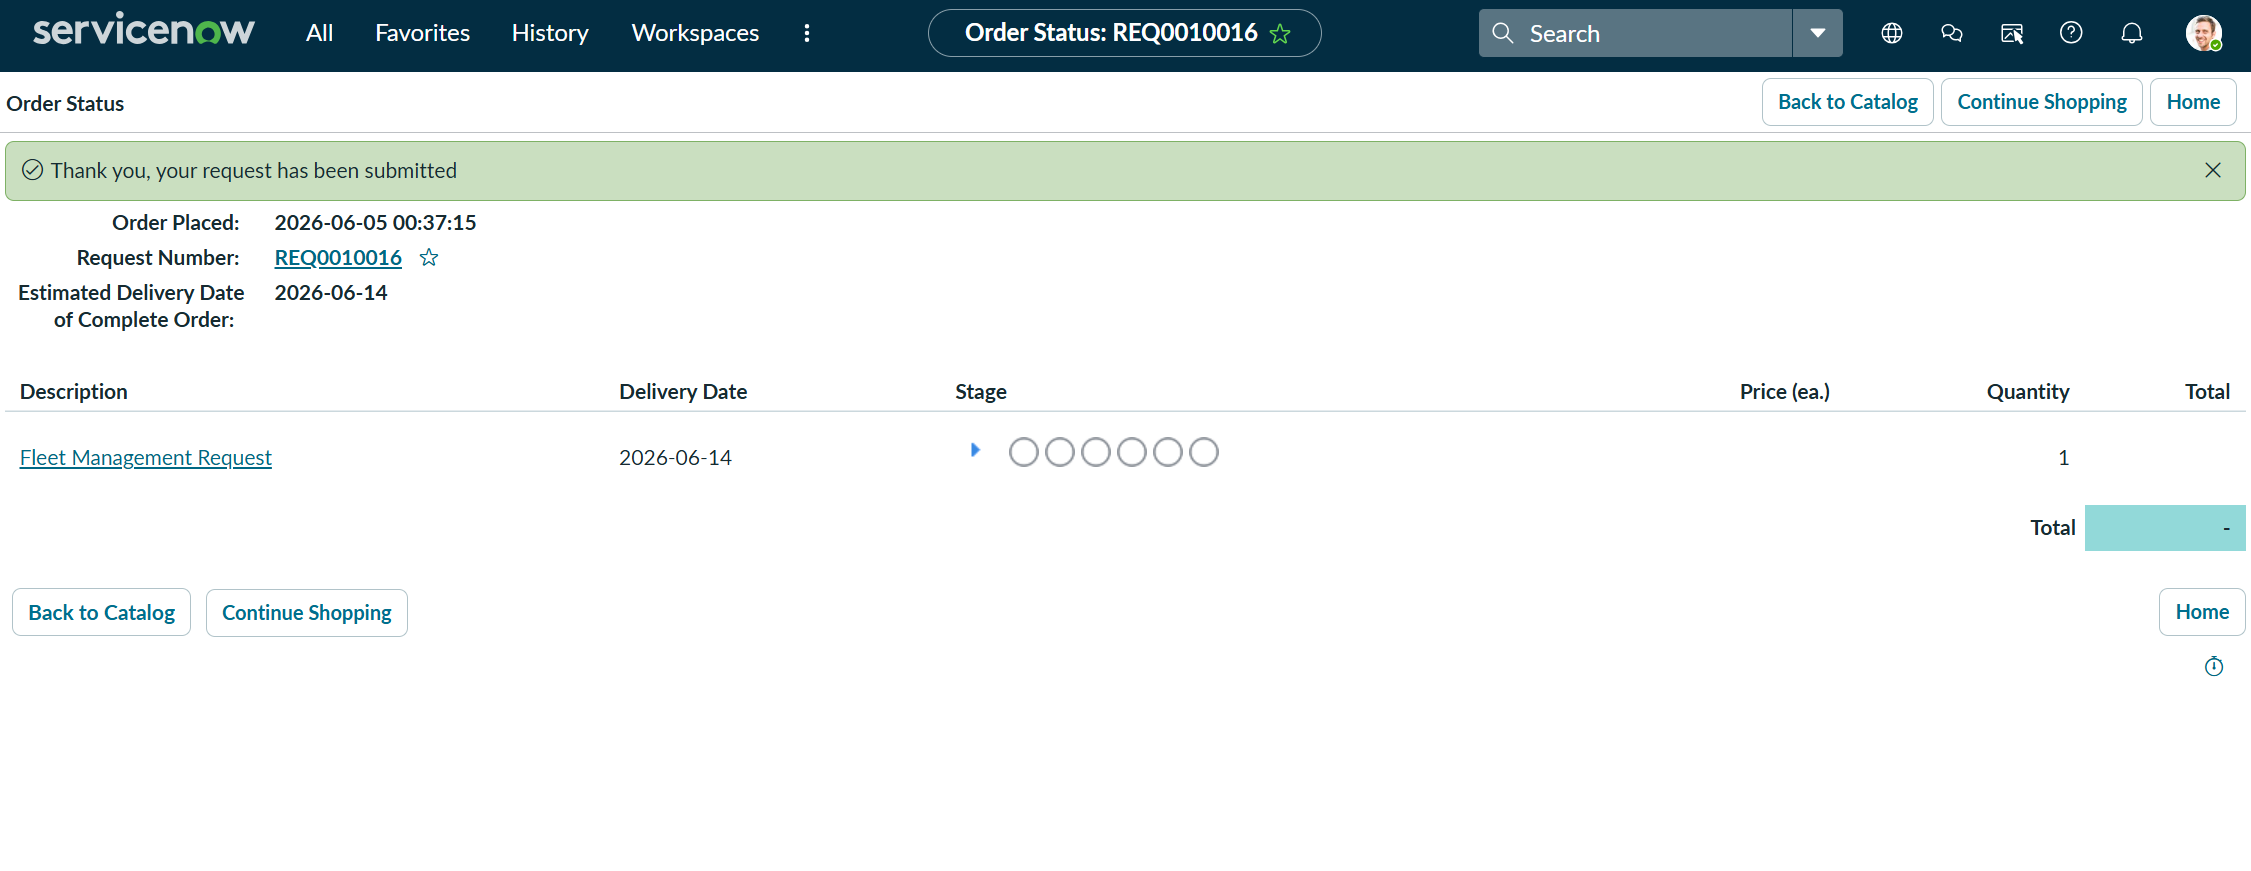
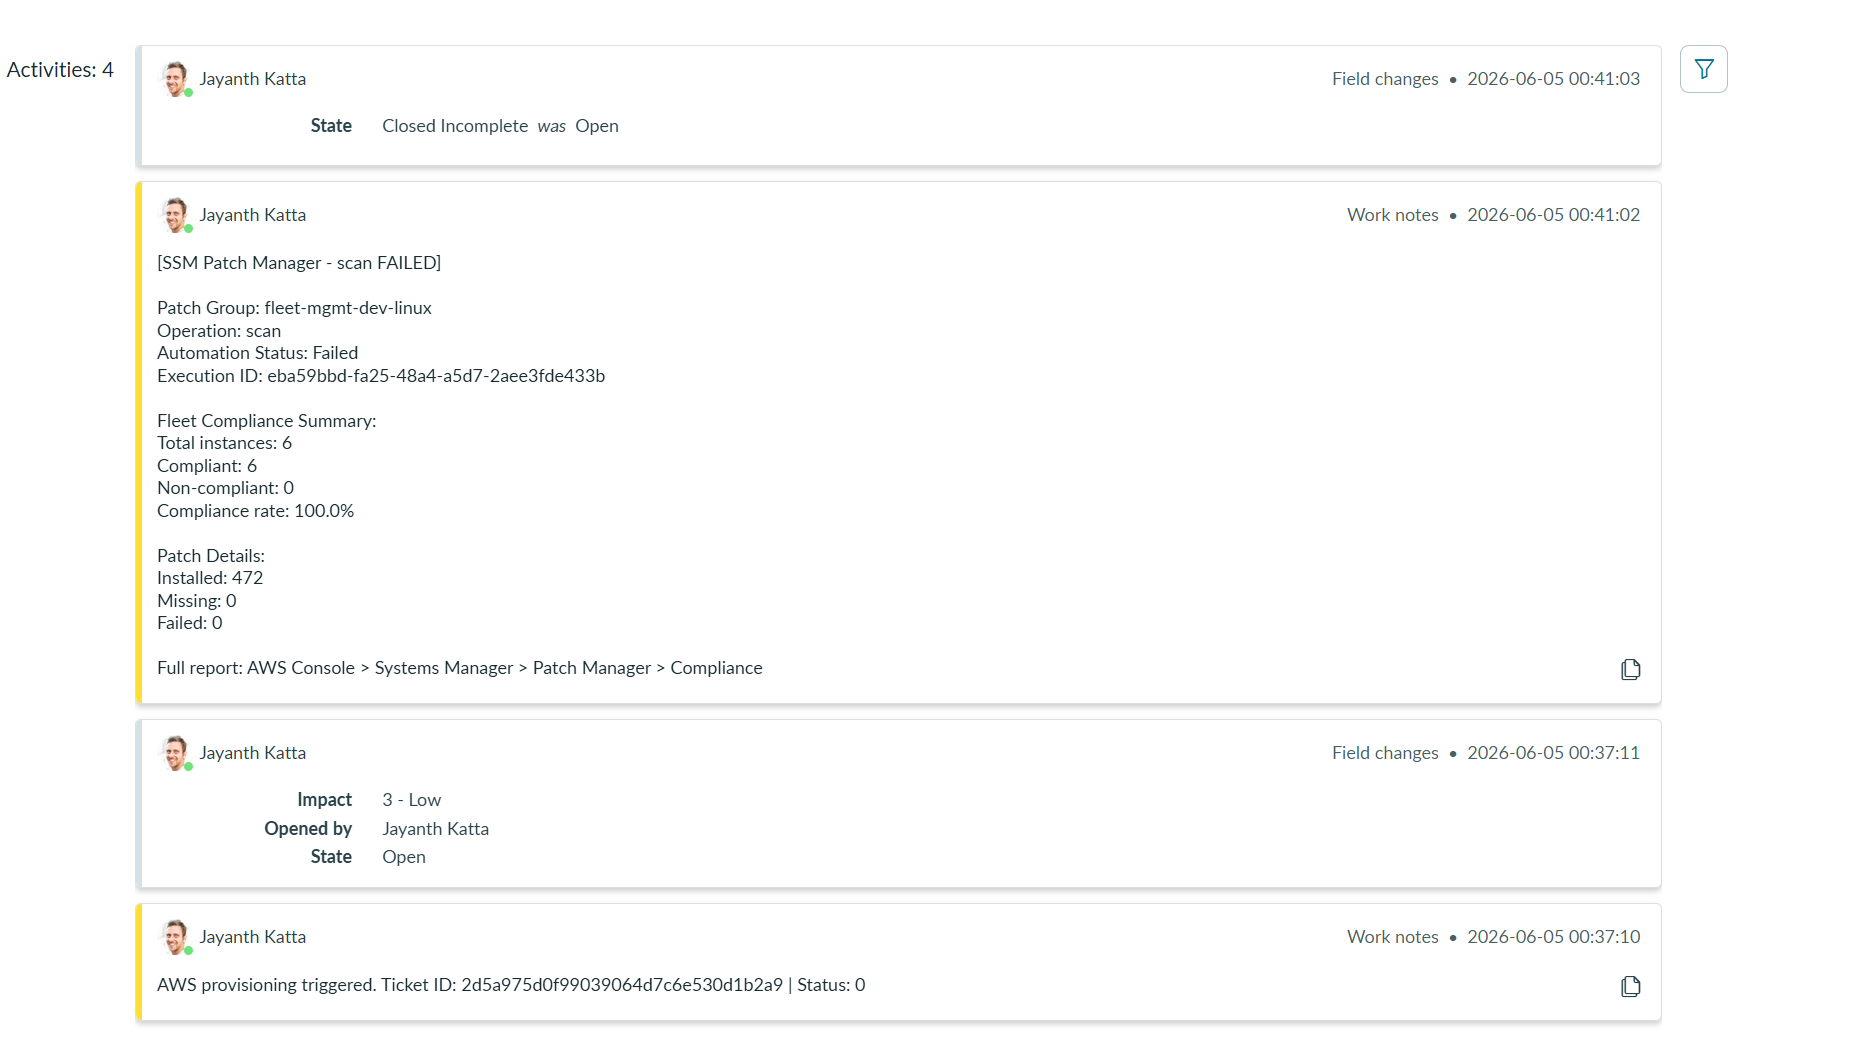
The status_updater Lambda calls back to ServiceNow and closes the ticket with a full compliance report — instance count, compliant/non-compliant, patch details, link to Patch Manager console.
No NAT Gateway — VPC Endpoints Only
This is the enterprise pattern. NAT gateways cost ~$32/month and route all SSM traffic through the public internet. SSM is an AWS service — there's no reason for that traffic to leave the AWS network.
| Endpoint | Purpose | Type |
|---|---|---|
ssm | Main SSM API — commands, parameters, registrations | Interface |
ssmmessages | Session Manager WebSocket channel | Interface |
ec2messages | Run Command delivery channel | Interface |
logs | CloudWatch Logs for Lambda and SSM agent | Interface |
s3 | Patch downloads and log uploads | Gateway |
aws_vpc_endpoint_service data source to filter to only supported AZs before creating subnets — otherwise Terraform fails with a cryptic AZ error.Validation and Evidence
Each row traces to a figure here. The lab was destroyed in June 2026; these are the results recorded then.
| Test | Expected | Actual | Status |
|---|---|---|---|
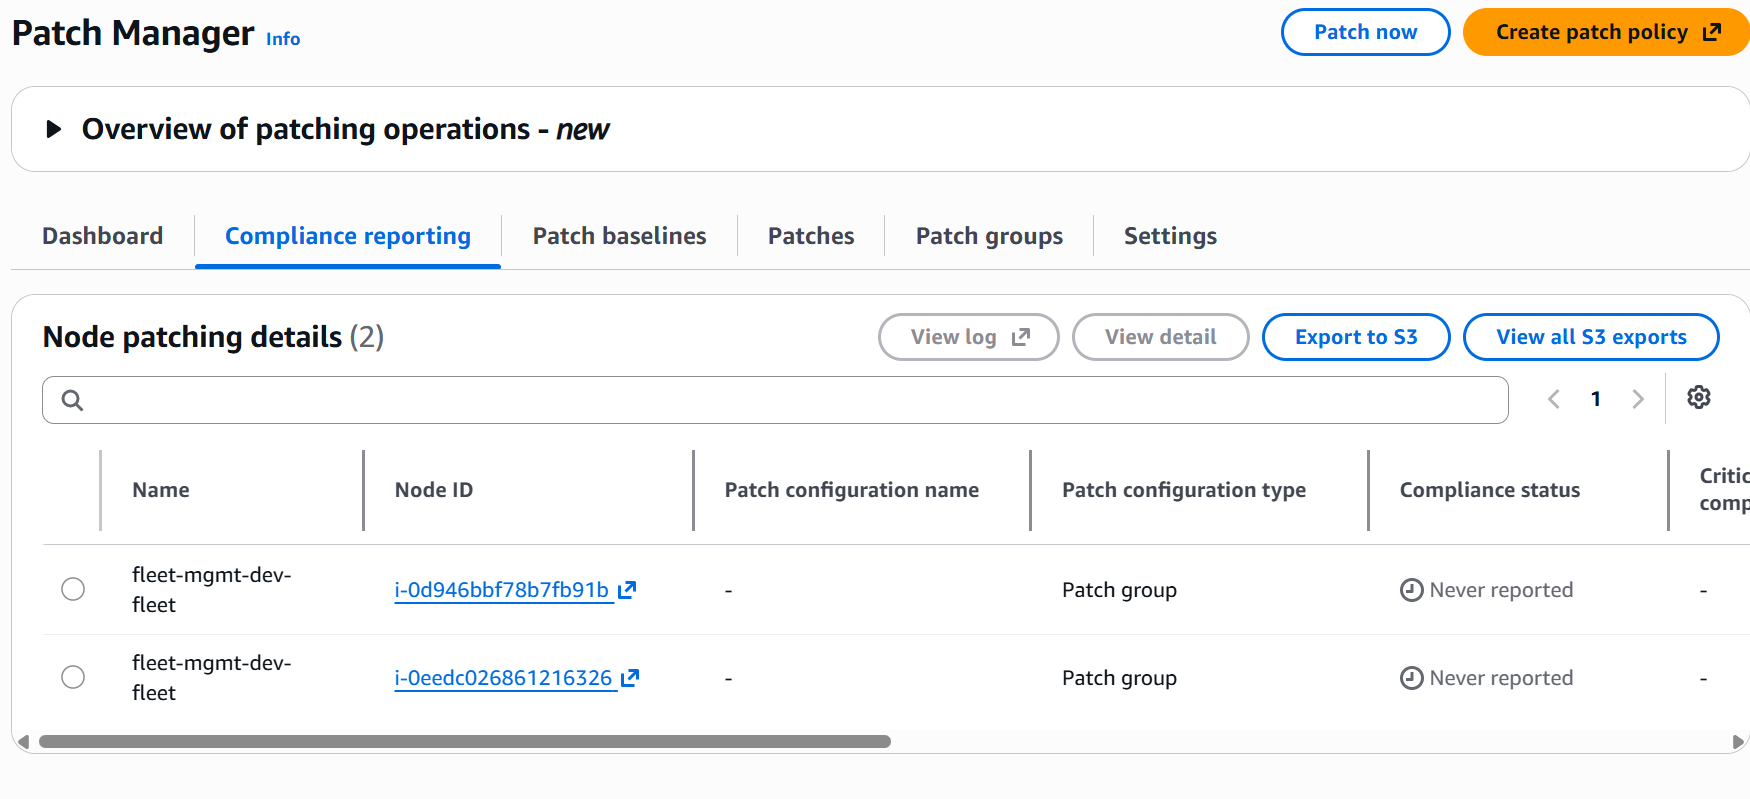
| Starting state is honest | Instances that have never been scanned report as such | Patch Manager showed Never reported before any scan ran | Pass |
| An unmanaged instance is invisible, not wrong | An instance with only a Name tag has no baseline | No PatchGroup, no ManagedBy, and no baseline assigned in Patch Manager | Pass |
| Onboarding tags it | The workflow applies the tags that make it managed | PatchGroup, ManagedBy and OnboardedAt all present afterwards | Pass |
| The fleet grows by one | Patch Manager counts the new instance with the others | Three instances listed, the manual one alongside the fleet | Pass |
| Patching reaches compliance | Every instance compliant, nothing missing | All three Compliant, MissingCount zero | Pass |
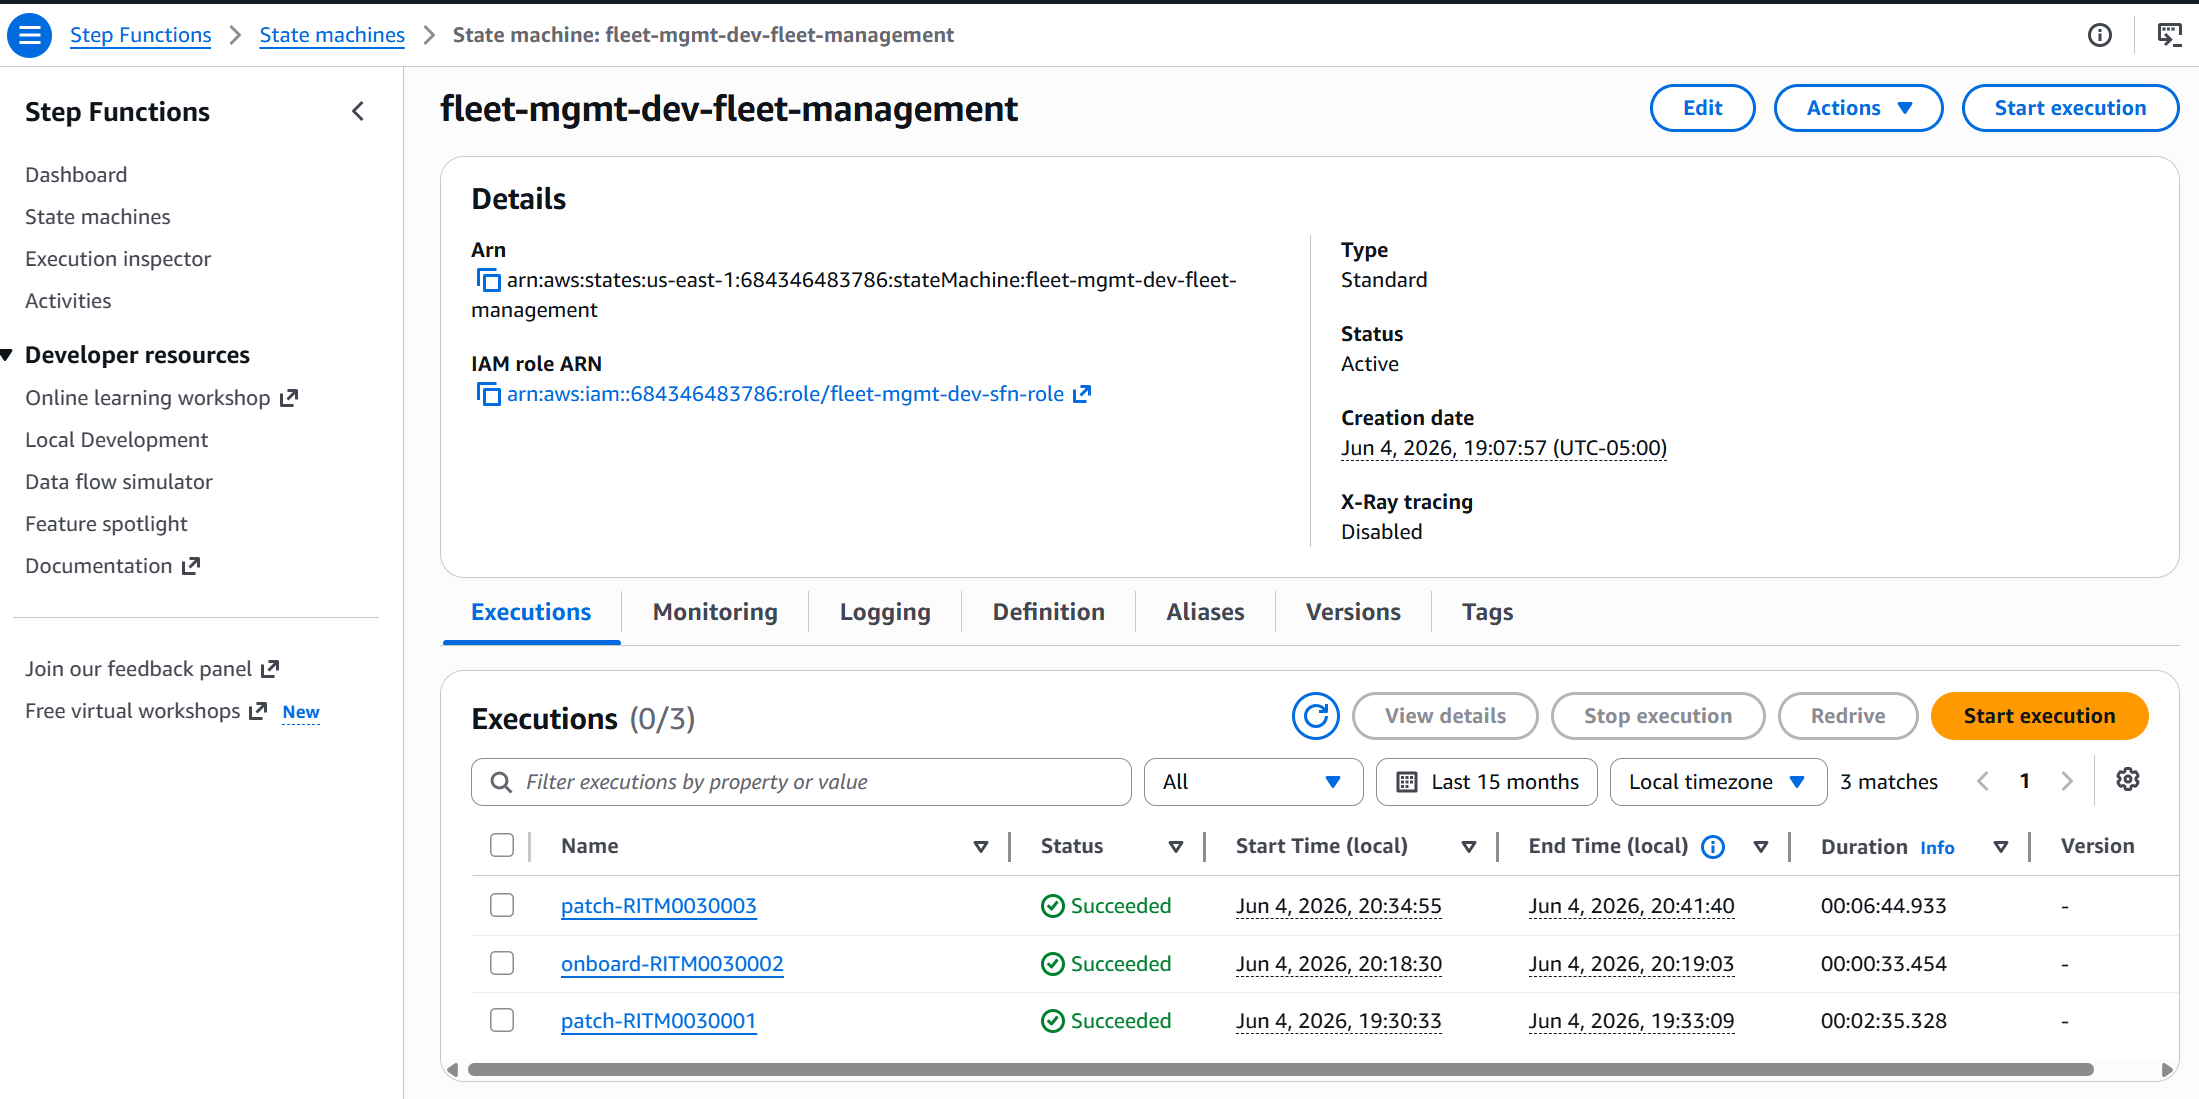
| Every request is auditable | One execution per request, each with a timestamp | All three executions SUCCEEDED in the executions list | Pass |
| The requester gets the answer | The ticket closes carrying the compliance result | Closed with the report in its work notes: 6 compliant, 472 patches installed | Pass |
The Demo — Watch It Work
Step 1 — Deploy: 80+ Resources, One Command
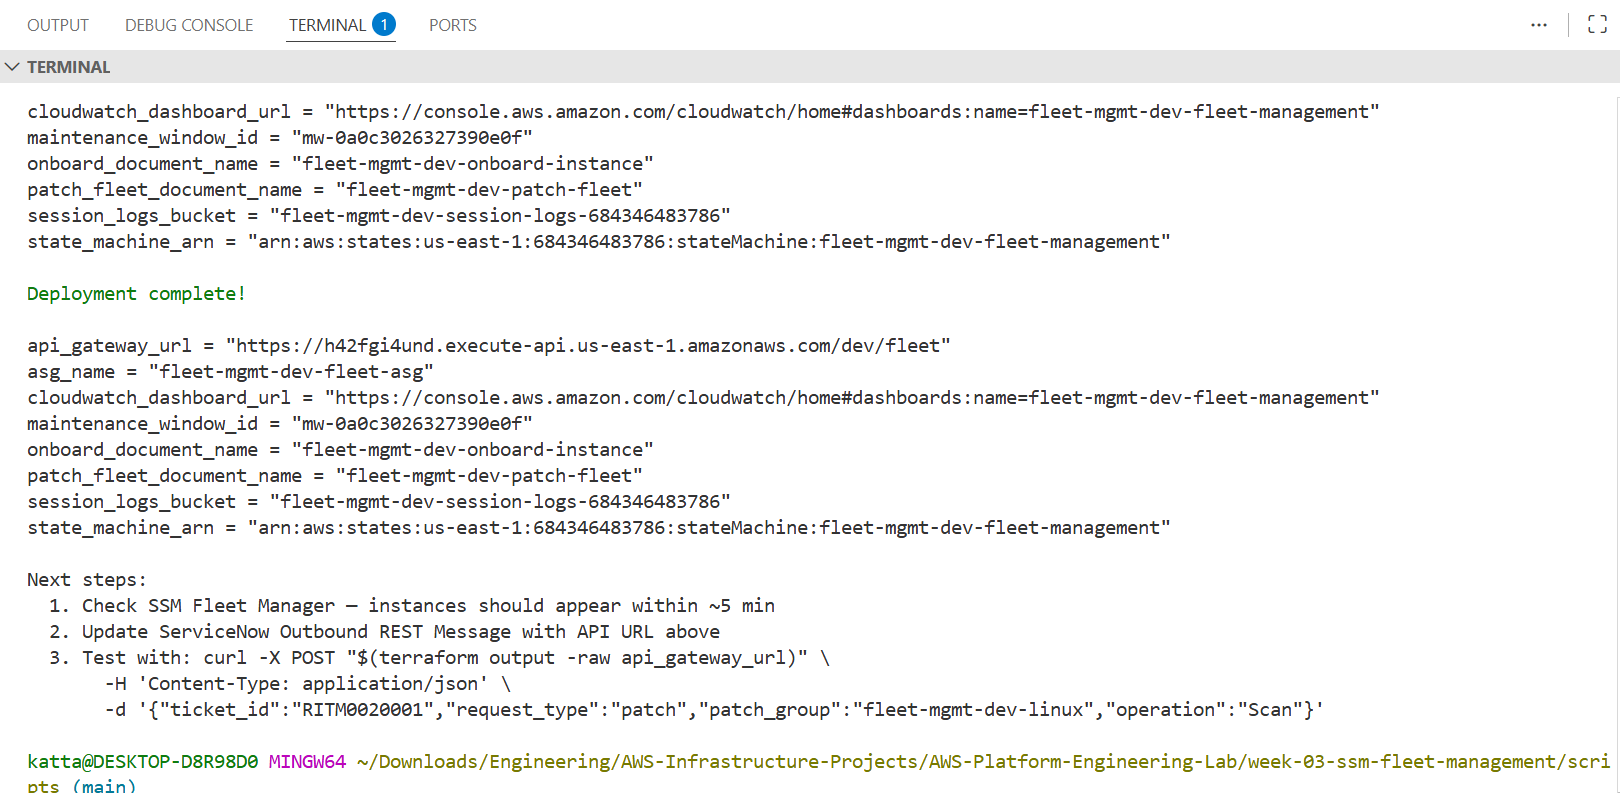
Terraform deploys the entire platform: VPC with SSM interface endpoints (no NAT gateway), EC2 fleet in private subnets, 4 Lambda functions, Step Functions state machine, patch baselines for Amazon Linux 2023 and Windows Server, maintenance window, and API Gateway.
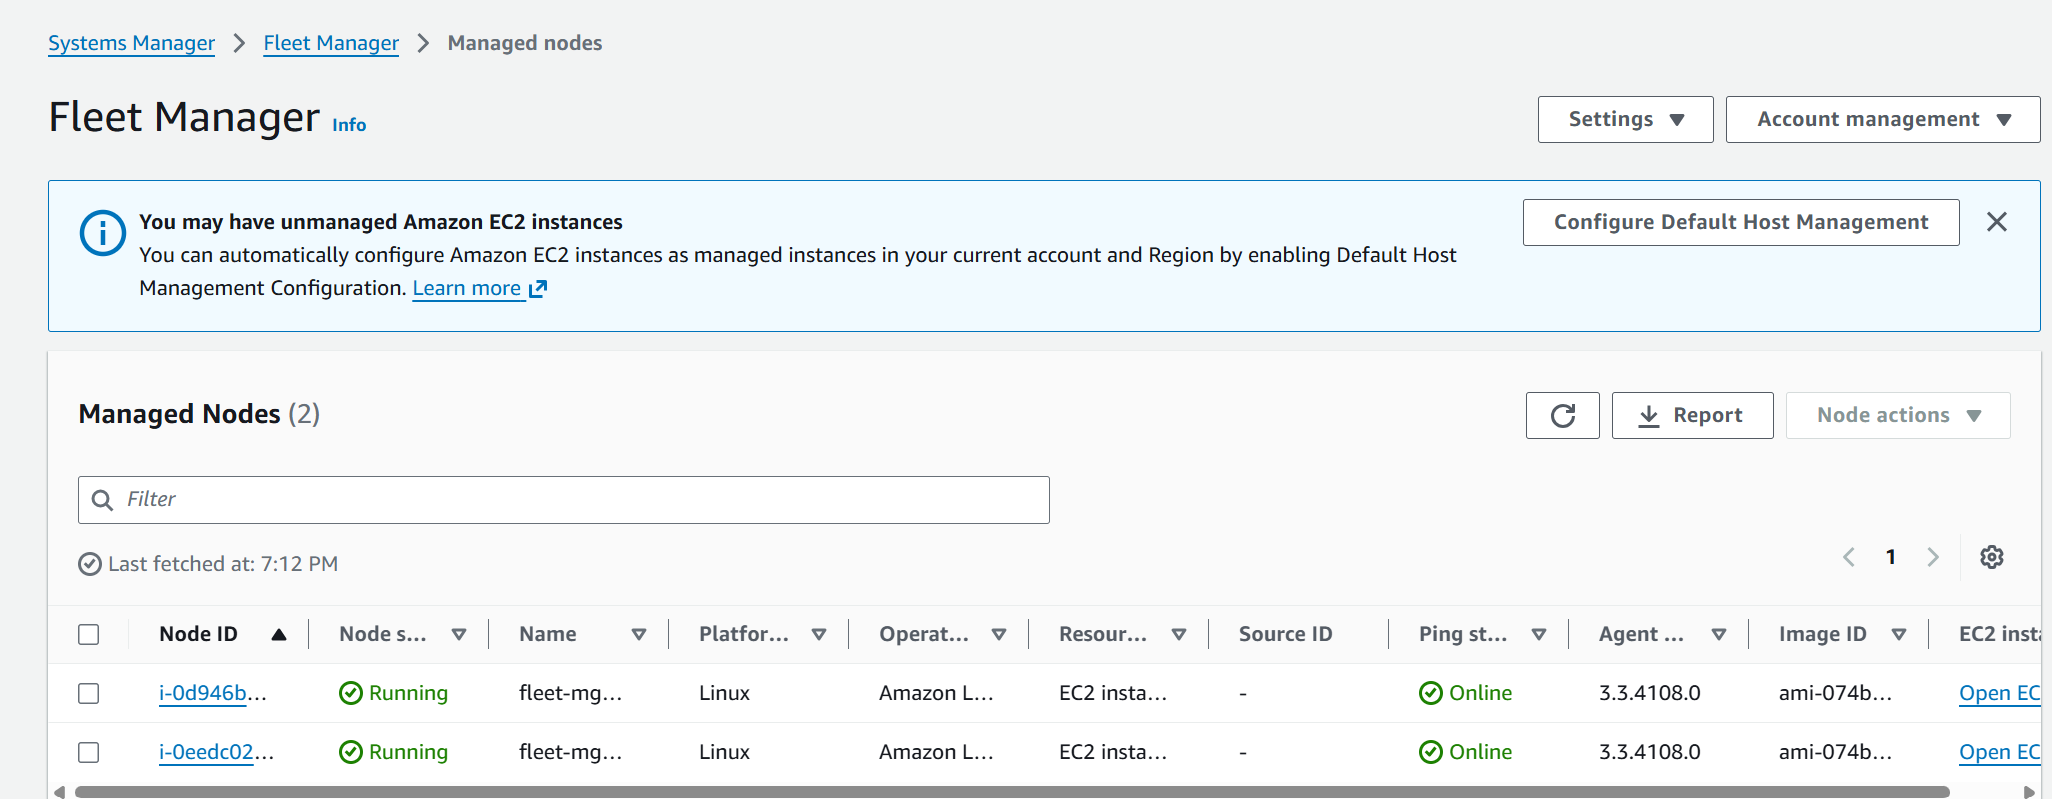
Step 2 — Fleet Manager: Instances Online
Within 5 minutes of launch, both ASG instances register with SSM automatically — no configuration needed. Fleet Manager gives a real-time view: online status, OS type, SSM agent version, last ping time. No SSH required to confirm they're healthy.
Step 3 — Patch Manager: The Before State
Fresh instances — no scan has run yet. This is the starting point the platform is designed to fix.
Step 4 — Simulate ServiceNow: Trigger a Patch Scan
A single curl command simulates what a ServiceNow business rule does — signs the payload with HMAC, posts to API Gateway, and starts a Step Functions execution.
BODY='{"ticket_id":"RITM0030001","request_type":"patch",
      "patch_group":"fleet-mgmt-dev-linux","operation":"Scan",
      "team":"platform-engineering","requested_by":"jay.katta"}'
SIG="sha256=$(echo -n "$BODY" | openssl dgst -sha256 -hmac "$SECRET" | awk '{print $2}')"

curl -X POST "$API_URL" \
  -H "Content-Type: application/json" \
  -H "x-servicenow-signature: $SIG" \
  -d "$BODY"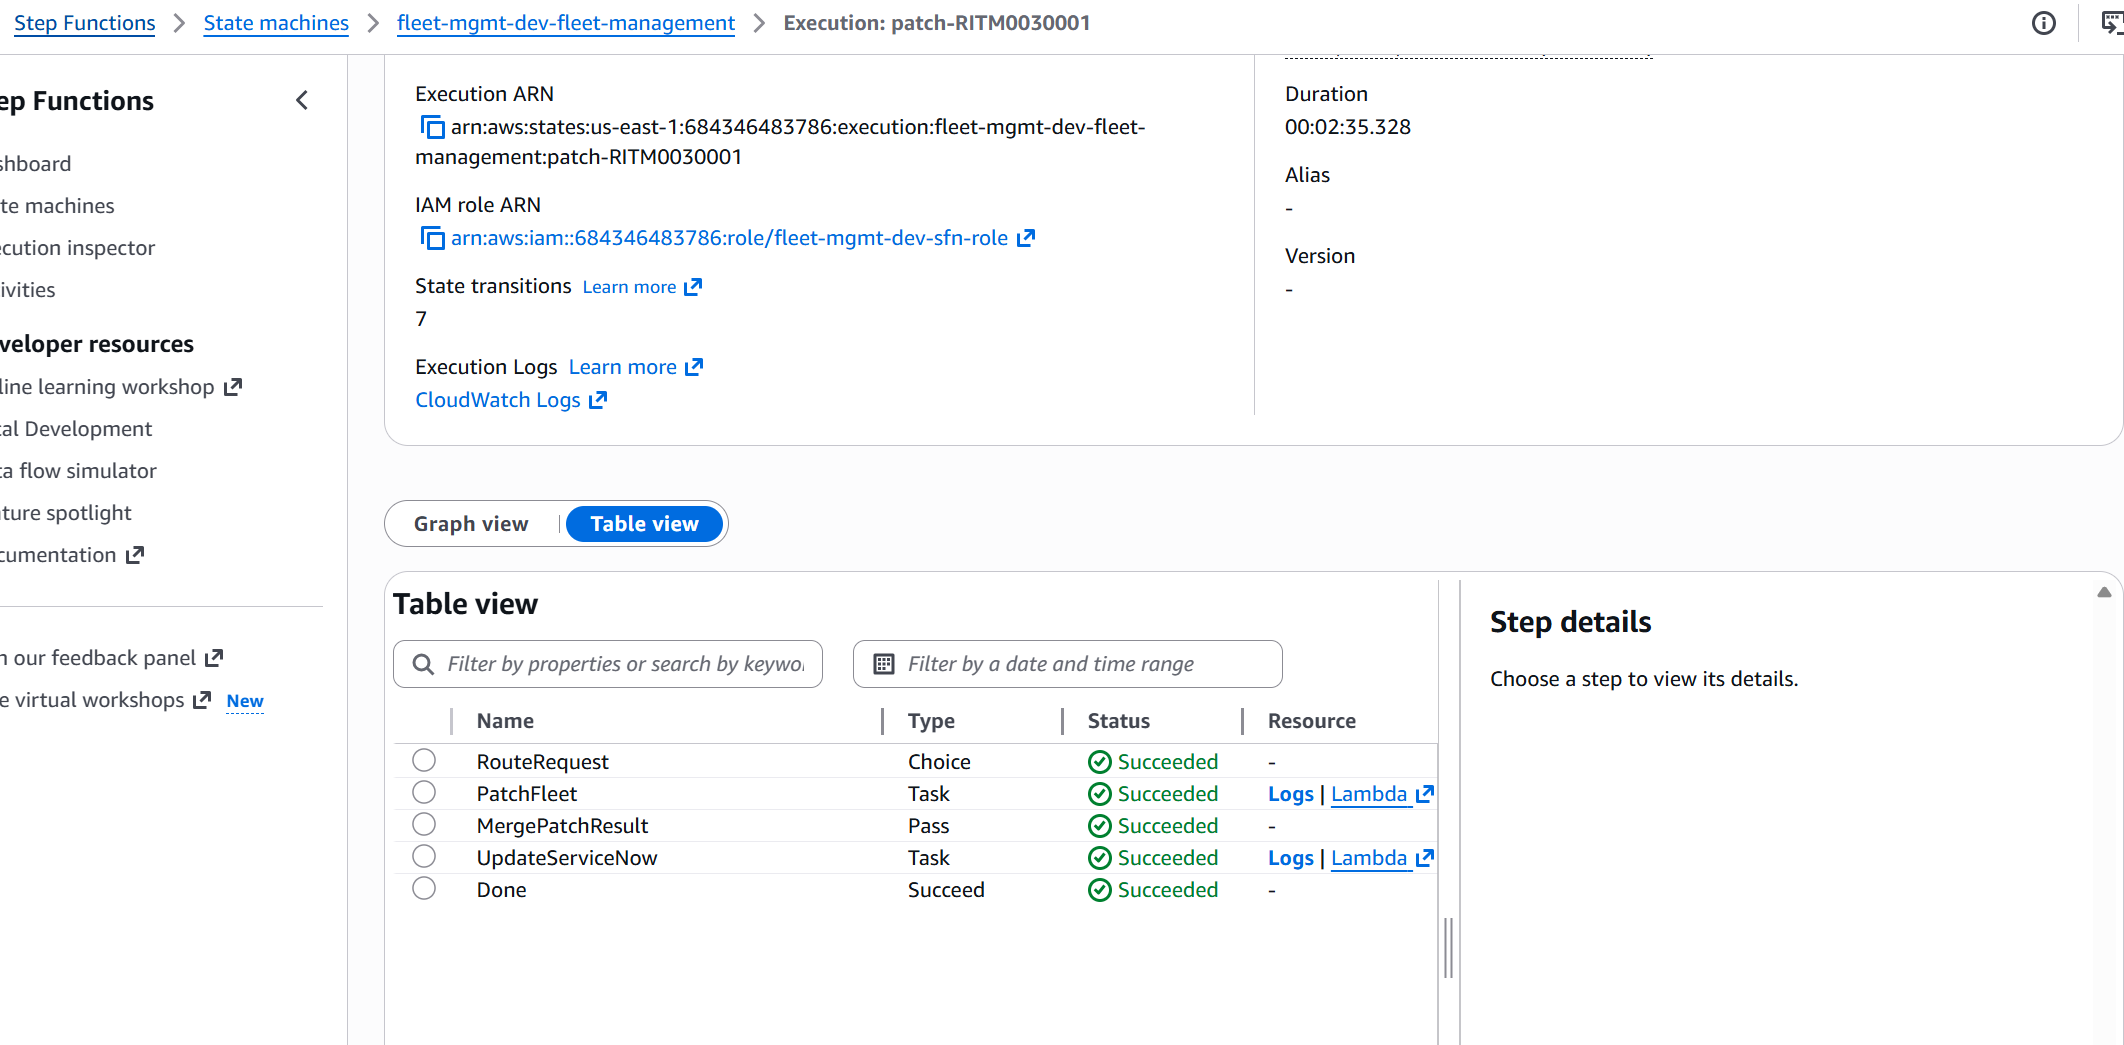
Full Audit Trail + CloudWatch Dashboard
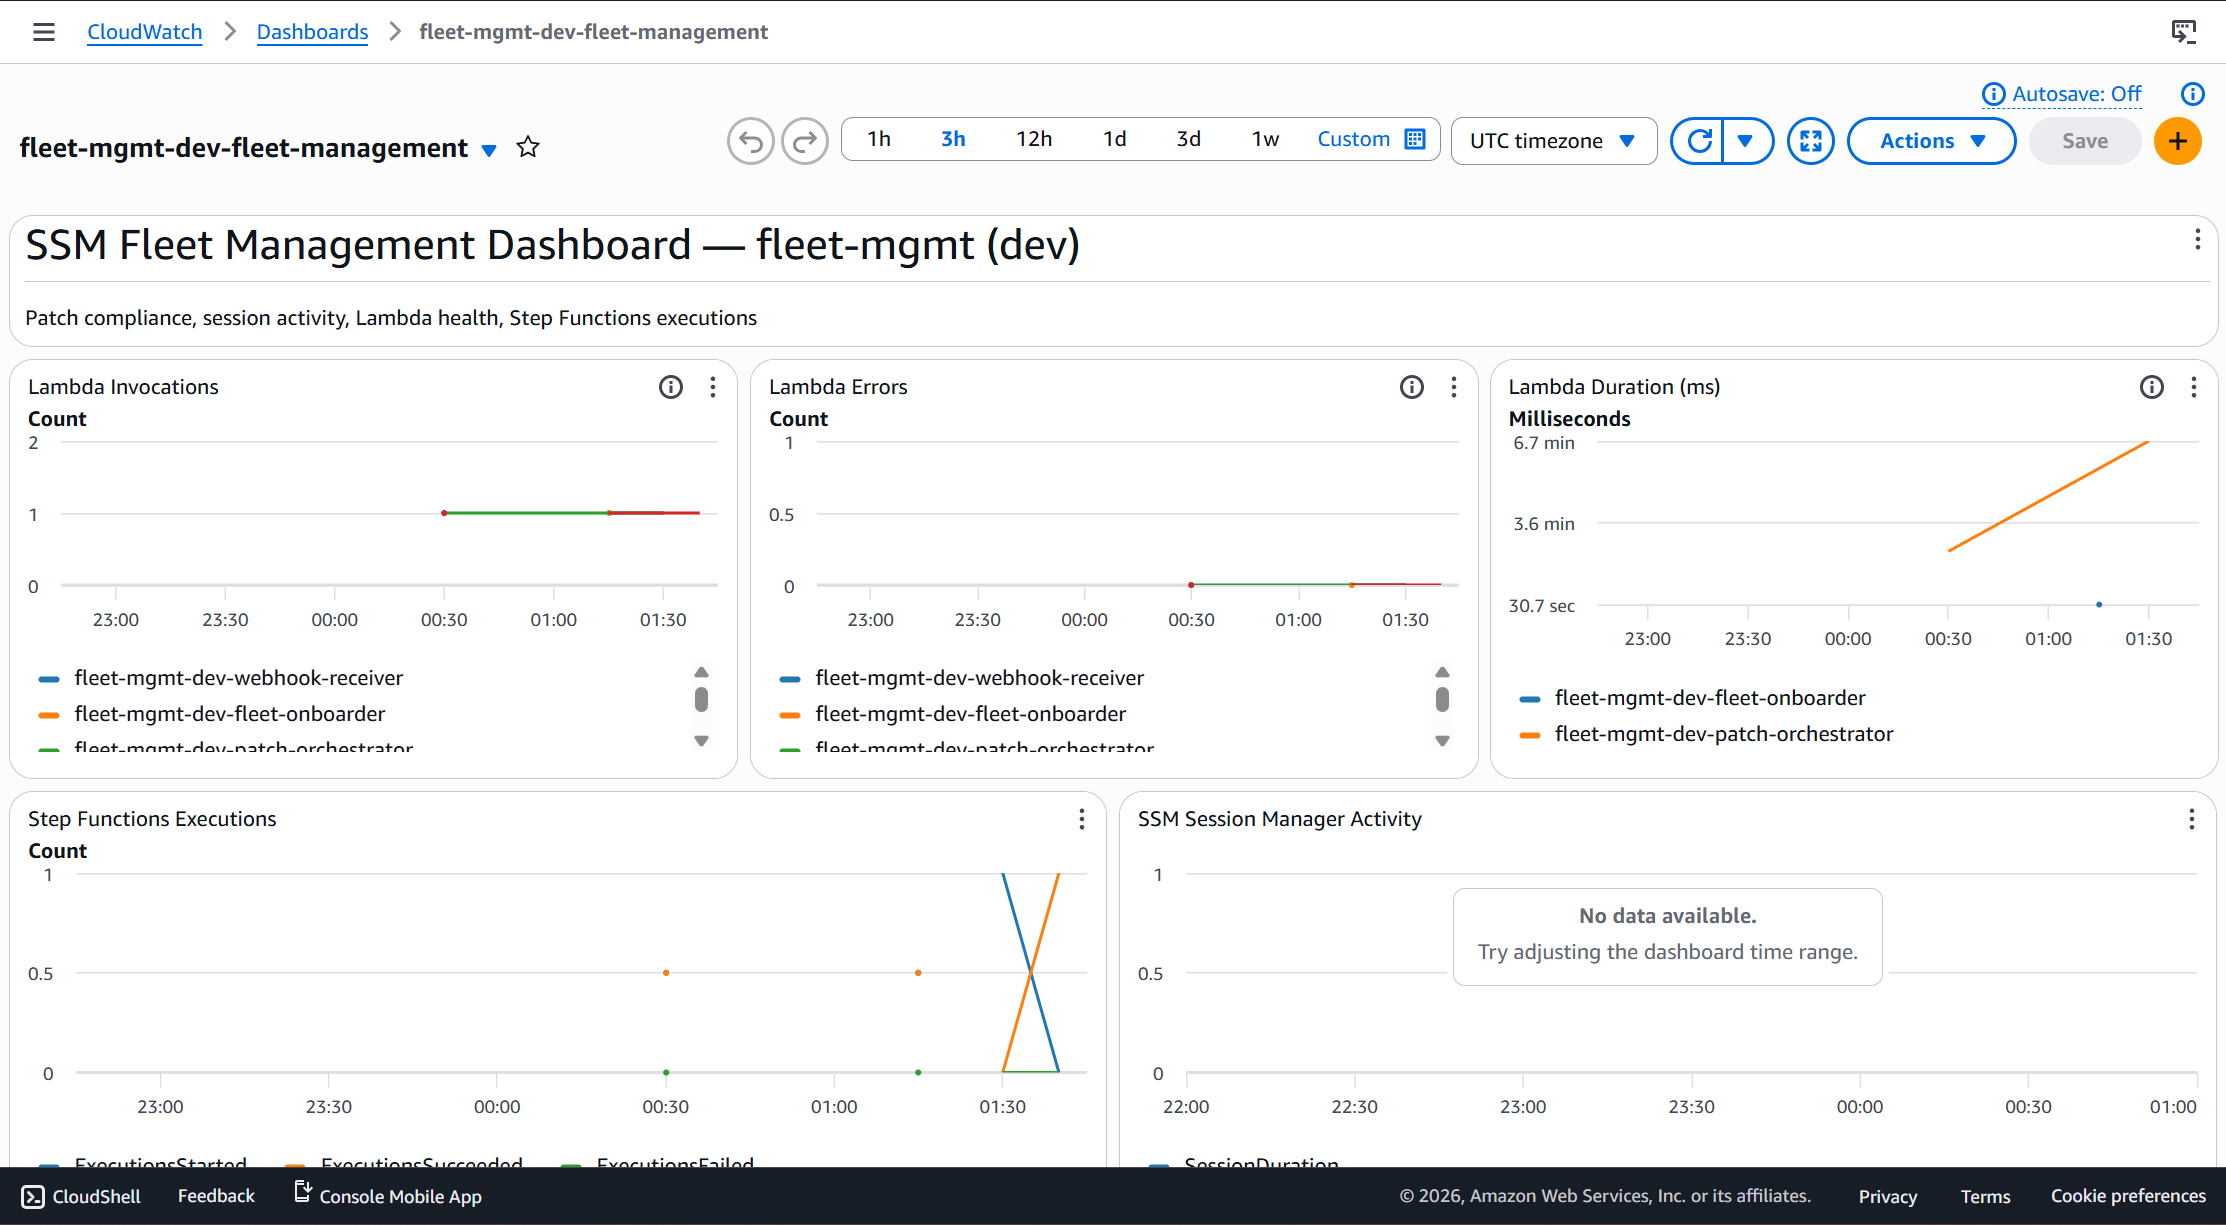
Every operation is traceable. Step Functions records every execution with the ticket ID, start time, and result. In production this maps directly to a ServiceNow RITM — you can look up any patch run and know exactly who requested it, when it ran, and what the outcome was.
Security and Cost
| Resource | Cost/Month (Running) | Cost (Destroyed) |
|---|---|---|
| EC2 t3.micro x2 | ~$17 | $0 |
| VPC endpoints x4 (interface) | ~$29 | $0 |
| CloudWatch | ~$2 | $0 |
| SSM (core features) | $0 | $0 |
| Lambda (minimal traffic) | ~$0 | $0 |
| S3 session logs | ~$0.02 | $0 |
| Total | ~$48/month | $0 |
sh scripts/cleanup.sh when done for the day.Troubleshooting and Lessons
Problem. Every SSM Parameter Store path the project tried to
create was rejected.
Root cause. AWS reserves any parameter path beginning
/ssm, case-insensitively, and the project was named
ssm-fleet — so every path began
/ssm-fleet/.
Resolution. Renamed the project to
fleet-mgmt.
Lesson. A project name becomes a path prefix, and a reserved prefix
is a naming decision you cannot undo cheaply later.
Problem. Terraform failed with a cryptic error while creating
VPC endpoints.
Root cause. Not every Availability Zone offers the Systems Manager
interface endpoints — us-east-1e does not — and
slice(AZs, 0, 2) was picking whichever two came first.
Resolution. Query aws_vpc_endpoint_service
and build subnets only in the zones that actually offer the endpoint.
Lesson. "Pick the first two AZs" assumes the zones are
interchangeable. For endpoints they are not.
Problem. The patch-fleet automation document failed
validation.
Root cause. CommandId is a reserved
output name in SSM Automation, and the document declared a custom output using
it.
Resolution. Renamed it to
PatchCommandId.
Lesson. Reserved names are rarely listed where you are looking; the
validation error is the documentation.
Problem. Instances would not launch at all.
Root cause. The AL2023 AMI snapshot needs at least 30 GB and the
launch template asked for 20.
Resolution. 30 GB, on gp2 — gp3 is not offered in every
us-east-1 zone either.
Lesson. The second AZ-availability surprise in one build. Zone
capability is worth checking before the template, not after it fails.
Problem.
InvalidAutomationExecutionParametersException on every
patch request from ServiceNow.
Root cause. ServiceNow sent scan;
SSM Automation accepts Scan or
Install, capitalised.
Resolution. Normalise the operation in the orchestrator rather than
relying on the sender's casing.
Lesson. Anything arriving from another system is input to be
validated and normalised, not a value to pass through.
Cleanup and Key Takeaways
Key Takeaways
SSM is a platform, not a tool. Seven distinct services — Fleet Manager, Patch Manager, Run Command, Session Manager, State Manager, Automation, Inventory — each solving a different operations problem. Most teams use one or two. Using all seven turns your EC2 fleet into a properly managed, audited, self-healing environment.
Tags are the source of truth for Patch Manager. No PatchGroup tag = no baseline = invisible to Patch Manager. The onboard workflow exists specifically to fix this for instances that predate your tagging strategy.
Session Manager eliminates SSH entirely. No port 22, no key pairs, no bastion hosts. Every session is logged to S3 and CloudWatch. For compliance-heavy environments this is not a nice-to-have — it's the only acceptable access pattern.
14 years as a DBA showed me what manual patching costs. An ops engineer patching 200 servers manually takes a full day — and produces no audit trail. This platform patches 200 servers in the same time it takes to patch 2, and every operation is traceable to a ticket ID and timestamp.
What's New in SSM Patch Manager (2025–2026)
Since this post was written, two updates are worth knowing:
- Patch now (on-demand) — you can now trigger a scan or install operation immediately on any managed node without setting up a maintenance window first. Useful for emergency patching outside the scheduled window.
- Quick Setup patch policies — AWS now recommends using Quick Setup to configure patching across your organization. It eliminates manual patch group setup and provides centralized control from a single place.
What's Next — Week 4
Week 3 automates patching. Week 4 answers the harder question: did it work across the entire estate?
Week 4 is a Fleet Intelligence Platform — using AWS Glue to crawl SSM inventory and patch data synced to S3, transform it with PySpark ETL, and make it queryable via Athena SQL. Instead of "2 instances compliant" you get: "Show me every instance that hasn't been patched in 30 days, sorted by severity."
All code available on GitHub: katta698/AWS-Platform-Engineering-Lab. Questions? Drop a comment below.
Comments