Business Challenge
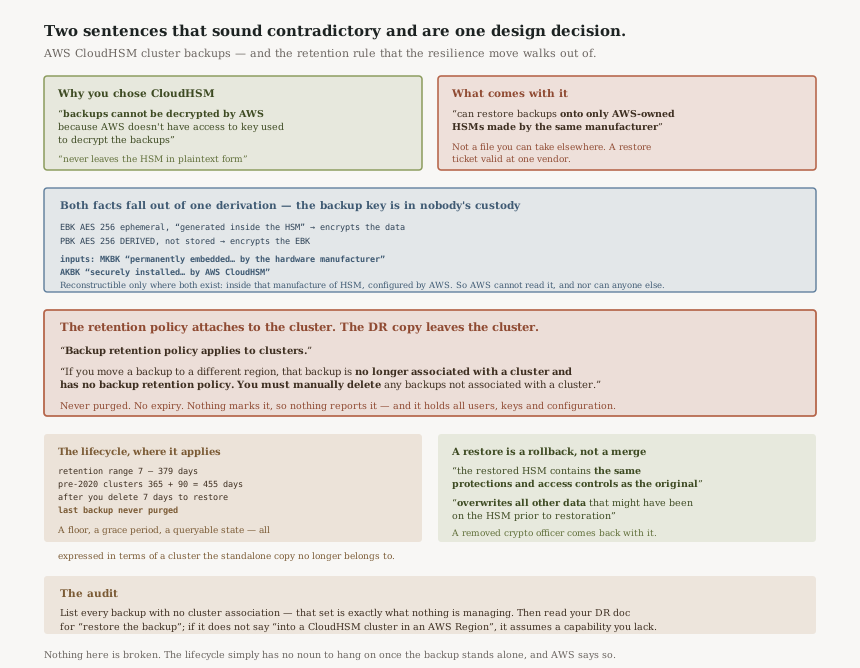
CloudHSM is where you put keys when "AWS can technically access this" is not an acceptable answer. The backup documentation makes the strong claim that justifies choosing it: “backups cannot be decrypted by AWS because AWS doesn't have access to key used to decrypt the backups.”
Four pages later, in the same section, is the constraint that comes with it: “AWS CloudHSM can restore backups onto only AWS-owned HSMs made by the same manufacturer.”
Neither of those is marketing and neither contradicts the other. Read together they tell you something precise about where you stand, and it is worth knowing before the day you need a restore rather than during it.
The policy attaches to the wrong noun for the thing you are about to do. “AWS CloudHSM purges backups based on the backup retention policy you set when you create a cluster. Backup retention policy applies to clusters.”
And then:
“If you move a backup to a different region, that backup is no longer associated with a cluster and has no backup retention policy. You must manually delete any backups not associated with a cluster.”
Copying a backup to a second Region is the obvious resilience move — it is why the operation exists. The side effect is that the copy leaves the lifecycle entirely. It will not be purged at 90 days or 379 days or ever; it does not appear in a retention report; and because “AWS CloudTrail reports backups marked for deletion” and nothing is ever marking this one, it will not show up there either.
A CloudHSM backup contains, in AWS's words, “all users, keys, and configuration from the original HSM”. An indefinitely retained copy of that in a Region nobody is looking at is a governance problem rather than a billing one.
FixTreat a cross-Region backup copy as a resource you own outright, with its own ticket and its own review date. If your key material has a retention requirement, that requirement does not travel with the copy — you have to re-implement it. Enumerate backups with no cluster association periodically; that set is exactly the set nothing is managing.
The encryption chain is documented in enough detail to see why both facts hold. The data is encrypted inside the HSM with an ephemeral key: “The EBK is an AES 256-bit encryption key generated inside the HSM when AWS CloudHSM makes a backup”, and “The data never leaves the HSM in plaintext form.”
That ephemeral key is itself encrypted by a persistent one, and the persistent one is derived rather than stored — from two inputs:
“A manufacturer key backup key (MKBK), permanently embedded in the HSM hardware by the hardware manufacturer.”
“An AWS key backup key (AKBK), securely installed in the HSM when it's initially configured by AWS CloudHSM.”
So the decryption key exists only where both of those inputs exist, which is inside an HSM of that manufacture that AWS has configured. That is simultaneously why AWS cannot read your backup — the key is not something AWS holds — and why no one else can restore it either.
The practical reading: this is not a backup in the sense of a file you could take elsewhere. It is a backup in the sense of a restore ticket valid at one vendor.
FixDo not write a disaster recovery plan whose fallback is "restore the HSM backup somewhere else". There is no somewhere else. If your requirement is genuine independence from AWS, the artifact that provides it is an exported key under your own wrapping, not a cluster backup — and that is a different design with different exposure, to be decided deliberately rather than discovered.
Two sentences that belong on the same page as your restore runbook.
“Because each backup contains all users, keys, and configuration from the original HSM, the restored HSM contains the same protections and access controls as the original.”
“The restored data overwrites all other data that might have been on the HSM prior to restoration.”
The first means a restore is a rollback of your user and quorum configuration, not just of key material. If you removed a crypto officer last month and restore a backup from two months ago, that officer is back, with whatever permissions they had.
The second means there is no merge. Restoring into a cluster that has been in use since the backup was taken does not combine the two sets of keys; it replaces one with the other.
FixMake the user and quorum configuration part of what you track alongside each backup, because restoring reinstates it. And before any restore into a live cluster, establish what has been created since the backup's timestamp — that is the set you are about to lose, and the service will not warn you about it.
Architecture
An HSM that encrypts its own backups, a derived key that exists only inside AWS-configured hardware of one manufacture, and a retention policy attached to clusters rather than to backups.
The key chain, and why it has exactly this consequence
| Key | What it is | Where it comes from |
|---|---|---|
| EBK — ephemeral backup key | “AES 256-bit”, encrypts the HSM's data | “generated inside the HSM when AWS CloudHSM makes a backup” |
| PBK — persistent backup key | “also an AES 256-bit encryption key”, encrypts the EBK | Derived, from the two inputs below |
| MKBK — manufacturer key backup key | A derivation input | “permanently embedded in the HSM hardware by the hardware manufacturer” |
| AKBK — AWS key backup key | A derivation input | “securely installed in the HSM when it's initially configured by AWS CloudHSM” |
Read bottom-up and the two headline facts stop being surprising. The PBK is not stored anywhere; it is derived, and both of its documented inputs live inside the HSM — one embedded by the manufacturer, one installed by AWS. AWS states the two consequences directly rather than leaving them to be worked out: “backups cannot be decrypted by AWS”, and restores go “onto only AWS-owned HSMs made by the same manufacturer”. The derivation is the reason both sentences can be true at once.
“A backup consists of only encrypted data. Before the service stores a backup in Amazon S3, the service encrypts the backup again using AWS Key Management Service (AWS KMS).”
The outer layer is the one AWS can manage; the inner layer is the one it cannot. Worth knowing which is which, because the outer layer is the one that shows up in your KMS key policies and CloudTrail, and it is not the layer protecting your key material.
Where backups live, and how durable that is
“AWS CloudHSM stores backups in a service-controlled Amazon Simple Storage Service (Amazon S3) bucket in the same region as your cluster”, with “a 99.999999999% durability level, the same as any object stored in Amazon S3”.
Service-controlled is the word to notice. The bucket is not in your account, so there is no bucket policy of yours on it, no object lock you can apply, and no lifecycle rule you can write. The only lifecycle control available is the retention policy, which is why its scoping matters so much.
The lifecycle numbers, in one table
| Control | Value | Notes |
|---|---|---|
| Retention period, settable range | 7 to 379 days | Set when you create a cluster; changeable later |
| Clusters created before 18 Nov 2020 | “90 days plus the age of the cluster” | AWS's example: a Nov 2019 cluster gets 365 + 90 = 455 days |
| Last backup | Never purged | “AWS CloudHSM does not delete a cluster's last backup” |
| After you delete a backup | 7 days to restore it | State becomes PENDING_DELETE; after seven days “you can no longer restore the backup” |
| Cross-Region copy | No policy at all | “You must manually delete” |
| Opting out of managed retention | Possible | “by contacting AWS Support” |
“To prevent a race condition, you should change the backup retention policy for the cluster before you restore a backup deleted by the service.”
Restoring a service-purged backup into a cluster whose policy still says to purge it is a loop you can lose. Change the policy first, then restore — the documentation says so, and the reason is that both actions are racing the same deadline.
Deleting a cluster is a two-step operation
“Before you can delete a cluster, you must remove all HSMs from the cluster.”
Which is a reasonable guard, and it means "delete the cluster" is not a single call that could be made by accident or by an over-broad automation. It also means the last backup survives the cluster, because nothing purges it.
Why This Architecture Holds Up
Deriving the backup key rather than storing it is the whole product
The alternative designs are both worse. A backup key stored by AWS means AWS can decrypt your keys, which defeats the reason CloudHSM exists. A backup key held only by you means a lost key is lost key material with no recovery, and AWS would be operating a service whose main failure mode it cannot help with.
Deriving it from a manufacturer-embedded value plus an AWS-installed value gives a third thing: the key exists reliably, in hardware, and in no one's hands. The cost is the restore constraint, and AWS states the constraint plainly instead of letting you discover it.
Not deleting the last backup is the right floor
“AWS CloudHSM does not delete a cluster's last backup.” A retention policy that could take you to zero backups is a retention policy that can destroy key material on a schedule nobody reviewed. Refusing the final deletion means the worst case of a misconfigured policy is a stale cluster rather than an unrecoverable one.
The seven-day window after an explicit delete is the same instinct applied to the manual path, and the
PENDING_DELETE state makes it queryable rather than implicit — you can list exactly
what is in the grace period.
Everything above is careful. The retention design has a floor, a grace period, a queryable state, and a CloudTrail record. All of it keys off the cluster association — and the one operation you perform specifically to survive losing a Region is the operation that severs that association.
So the most carefully protected copy and the least governed copy are produced by the same resilience decision. Nothing is broken; the lifecycle simply has no noun to hang on once the backup is standalone, and AWS says so rather than pretending otherwise.
Stating the restore constraint in the security section is the honest placement
“AWS CloudHSM can restore backups onto only AWS-owned HSMs made by the same manufacturer” appears in the page explaining backup encryption, next to the derivation that causes it — not buried in a limitations list. That is the difference between a documented consequence and a surprise: the reader who understands the key chain already expects the sentence by the time they reach it.
Key Architecture Decisions
| Decision | Choice | Reasoning |
|---|---|---|
| Cross-Region backup copies | Own them explicitly, with a review date | They have “no backup retention policy” and you “must manually delete” them. |
| DR plan fallback | Never "restore the backup elsewhere" | Restorable “onto only AWS-owned HSMs made by the same manufacturer”. |
| Genuine vendor independence | Exported keys under your own wrapping, decided deliberately | A cluster backup cannot provide it, by construction. |
| Retention period | Set it from your key-material requirement | Range is 7 to 379 days; the default for old clusters is age-dependent. |
| Before restoring into a live cluster | Inventory what was created since the backup | The restore “overwrites all other data” — there is no merge. |
| User and quorum changes | Track them against backup timestamps | A restored HSM has “the same protections and access controls as the original”. |
| Restoring a service-purged backup | Change the policy first | AWS names the race condition explicitly. |
| Deleting a cluster | Expect two steps | “you must remove all HSMs from the cluster” first. |
| Expecting bucket-level controls | Do not plan on them | The bucket is “service-controlled”; retention policy is the only lever. |
| Opting out of managed retention | Only with a replacement process | It is available “by contacting AWS Support”, and removes the floor's usefulness. |
The audit worth running
List every backup with no cluster association. That set has no retention policy, no expiry and no deletion record, and each member contains “all users, keys, and configuration from the original HSM”. If the list is longer than your team expects, each extra entry is a copy of your key material that somebody made for a good reason and nothing has governed since.
Then read your DR document for the phrase "restore the backup". If it does not say "into a CloudHSM cluster in an AWS Region", it is assuming a capability that does not exist.
Closing Thought
The two sentences this post is built on look like a contradiction and are a single design decision seen from two sides. The backup key is derived inside hardware from a manufacturer value and an AWS value, so it is in nobody's custody — which is exactly why AWS cannot read your backup, and exactly why nothing outside AWS can restore it. You cannot have the first property without the second. The documentation is clear about both and puts them on the same page.
What is genuinely easy to miss is the retention scoping, because it runs the other way from intuition: the copy you make to protect yourself is the copy the service stops protecting. Every other part of the lifecycle has a safeguard — a floor on the last backup, a seven-day grace period, a queryable pending state, a CloudTrail record — and all of them are expressed in terms of a cluster the standalone copy no longer belongs to.
#86 was about two operations whose names suggest the same reach and do not have it. This is about one operation whose purpose is resilience and whose side effect is leaving the lifecycle. In both cases the documentation says so; it just says so somewhere other than where you were reading.
Security & Identity — AWS Payment Cryptography: why importing the same key twice leaves you with two key ARNs on separate lifecycles, how TR-31 modes of use constrain what a key is permitted to do from the moment it is created, and what an alias buys that a key ARN cannot.
Official AWS Reference
- Security of cluster backups — the statement that AWS cannot decrypt backups, the EBK and PBK and their sizes, the MKBK and AKBK derivation inputs, the restriction to AWS-owned HSMs of the same manufacturer, what a restored HSM inherits, the overwrite behaviour, and the second encryption with AWS KMS
- Configure AWS CloudHSM backup retention policy — that the policy applies to clusters, the loss of any policy when a backup moves Region and the resulting manual deletion requirement, the 7 to 379 day range, the pre-November-2020 age-based policy and its 455 day example, the last-backup floor, the CloudTrail reporting of backups marked for deletion, the race condition warning, and opting out via Support
- Delete AWS CloudHSM cluster backups — the seven-day hold after deletion, the point after which restoration is impossible, and the PENDING_DELETE state
- AWS CloudHSM cluster backups — what a backup contains, the service-controlled S3 bucket in the cluster's Region, and the durability level
- Deleting an AWS CloudHSM cluster — the requirement to remove all HSMs first
- Copy backups to a different Region — further reading on the operation itself; no claims in this post are drawn from it
- Restore backups — further reading on the restore procedure; no claims in this post are drawn from it
Comments